
Table of contents of the article:
For years, our website has struggled with a paradox familiar to anyone in our profession: we spend our days optimizing clients' infrastructure, and the website that showcases that work always ends up at the bottom of the priority list. The time we should have dedicated to managedserver.it was, rightly, dedicated to those who pay us to do it.
For a long time, the go-to solution was an external optimization service: Nitropack . A yearly subscription, a plugin, a half-hour setup, and PageSpeed Insights mobile tests returned scores above 90. Convenient, fast, and with a toll-free number to display.
Then we started looking at how that number was obtained, and we lost the desire.
Why we stopped trusting the score
By analyzing the behavior of the page served with Nitropack, we realized that, in our case, some of the techniques adopted produced a result that we perceived as much closer to a test optimization than to a true optimization of the user experience.
In particular, we observed several aspects that did not convince us:
- JavaScript returned outside the measurement window. The scripts weren't necessarily made lighter or faster: some of the work was executed after the user's first interaction or with a sufficient delay to move them past the most relevant measurement phase. The Total Blocking Time was thus very low, but part of the load was simply shouldered later by the browser.
- Different behaviors during measurements. After analyzing the responses and the overall behavior of the page, we felt that the test result did not accurately represent what we wanted to offer to a normal visitor.
- A chain of collateral problems. Cookie consent that kicked in late, widgets that appeared stutteringly, images replaced in unpredictable ways, and a significant reliance on a CDN and a third-party service to serve our own site.
- No commensurate benefit on slow networks. The most important point: on a poor 4G connection, which is what many people actually use when reading a website on their phones, the page wasn't necessarily faster in the way the summary score might suggest.
In short, the score had ceased to be a sufficient indicator for us. It had become a number we wanted to better understand, not simply chase.
So, a week before our annual renewal deadline, we decided to do what we've always recommended to our customers: sit down, measure, and optimize by hand. Our stated goal was to cancel our subscription without losing performance and, hopefully, actually improve it.
This article tells what we did, in the order we did it, with the real numbers we measured.
The starting point
The site's stack is the one we recommend for WordPress clients who want performance: nginx on the front with TLS, HTTP/2, and HTTP/3, Varnish as the page cache, an internal nginx as the backend, PHP-FPM with a dedicated pool, and MariaDB. The theme is Astra, the builder is Elementor, with Autoptimize for aggregating CSS and JavaScript.
With Nitropack disabled, the mobile home page on PageSpeed Insights fluctuated between 76 and 86 points , with a Largest Contentful Paint between 3,8 and 5,3 seconds depending on the run. The desktop was between 97 and 100.
The field data, from the Chrome User Experience Report, was already green: LCP 0,7 seconds, INP 73 milliseconds, CLS 0. Real users were fine. It was the lab that wasn't aligned, and the lab is also what many users, technicians, and potential customers look at when they want to understand how fast a site is, but above all, it becomes important when faced with slow mobile connections.
There's a paradox and cognitive bias among those who work on web performance optimization , which is to give exclusive weight to field data, the CRUX "Chrome Real User Experience" data, and completely ignore laboratory data, the LABS data. To fully understand the difference, we recommend this article: Core Web Vitals and CRUX data.
However, the CRUX data is only the average of user navigation and their connections, so if we are faced with a website that is viewed 90% by users in Milan and Rome who have fast connections, fiber and 5G everywhere, we will have optimal CRUX values even when faced with a really slow site that, if browsed from some mountainous village in Sardinia with a slow 4G connection, would not exceed the CRUX data in the slightest.
The important mindset is therefore to certainly give value and importance to CRUX data but at the same time always keep an eye on LABS data.
An important detail before listing the changes: none of the changes we introduced intentionally change the HTML to achieve a better result exclusively for the tester . Our goal was to ensure that what Lighthouse measures is as representative as possible of the page a visitor actually uses.
How we measured
A significant part of the work was dedicated to measurement, because without a reliable method it is easy to end up optimizing for noise.
Local Lighthouse, not just PageSpeed Insights
PageSpeed Insights has some practical limitations when running dozens of tests in a row. That's why we also equipped ourselves with Lighthouse locally , using the system Chrome browser, in Headless mode on Linux Ubuntu, and in WSL on Windows, so we can run measurement series and analyze the traces directly.
Observed versus simulated
Lighthouse on mobile applies a simulation of network and CPU conditions to a recording. The simulated LCP value, which contributes to the score, also depends significantly on variables that may be less obvious when looking at the final result alone.
Among these, we identified above all the overall size of the document and the CPU work that precedes the rendering of the LCP element.
The bimodality of measurements
We also discovered that some of the tests fell into a sort of “slow mode” : the first frame was served after the second, while the main thread appeared to have already painted the page well before.
This taught us something important: a single run of Lighthouse tells us very little . For the most delicate interventions, we therefore worked on series of multiple tests, observing the distribution of results rather than relying on the best or worst number.
PageSpeed Insights' raw JSON
To truly compare our measurements to Google's, we also analyzed the full output produced by Lighthouse via PageSpeed Insights, looking at the LCP breakdown into TTFB, load delay, load time, and rendering delay.
This breakdown was the compass for much of the subsequent work.
The interventions, one by one
1. One critical CSS per page and per device
The first structural intervention concerned the CSS.
The site's aggregated CSS weighs hundreds of KB, and a blocking stylesheet of that size is one of the main enemies of First Contentful Paint. The classic solution is to insert the critical CSS inline and then load the full stylesheet.
On a site built with Elementor, however, there's a complication: each page has rules for individual elements, with specific identifiers. Therefore, a generic critical CSS shared across all pages isn't enough. We need one per page, and in our case, one differentiated by device, because Astra's mobile header and desktop header behave differently.
We've built a repeatable process that now allows us to complete the task in about ten minutes per page:
- generation via Penthouse with a high viewport, 2200 pixels, so as not to lose the rules relating to the sections just below the fold;
- JavaScript is active during generation, because Astra applies some necessary classes to the mobile head via script;
- pruning based on real coverage, measuring with Chrome which rules are actually used;
- Reintroduced the necessary pagination rules for Swiper, to prevent carousels from stacking vertically before the full CSS arrives;
- visual check above the fold on multiple viewports;
- CLS measurement after deployment on both mobile and desktop.
The result was a drop from about 130 KB of candidate critical CSS to the 55-60 KB actually needed.
Today, 47 pages of the site have their critical CSS mobile and desktop, with the full sheet deferred and without unnecessary blocking CSS requests.
Critical CSS has also exposed some flaws that were previously hidden by blocking full-page loading. For example, hero images lacking the pre-reserved space: when the first rendering occurred later, the problem wasn't obvious; when rendering occurred earlier, however, it became visible in the form of layout shifts, which impacted not only the aesthetically unappealing visual rendering but also the CLS Cumulative Layout Shift metric.
Three variations of the same problem were fixed with three simple CSS rules.
2. content visibility to avoid paginating what you can't see
An Elementor homepage consisting of 34 sections and approximately 3.300 elements requires the browser to do significant style calculation and layout work, even when a large portion of those elements are thousands of pixels below the visible window.
With content-visibility: auto and a contain-intrinsic-size measured section by section we allowed the browser to skip rendering what is not yet close to the viewport.
The heights were actually measured, for each page and for each device, after having scrolled through the entire document, because lazy-loading images can change the final height of the sections.
On mobile, the rule kicks in from the first section that exceeds approximately 1400 pixels in total. On desktop, it kicks in from the fifth. The footer, which reaches approximately 4.400 pixels in height on mobile , is excluded from the initial rendering practically everywhere.
There was also an interesting side benefit: a font used exclusively within non-rendered sections need not be downloaded until it is actually needed.
3. Understand who forces the layout
By instrumenting the browser's geometry APIs, including getBoundingClientRect(), we found that some Elementor handlers were forcing the layout of sections excluded from the initial rendering as early as a few hundred milliseconds after loading.
Among these were the stretch section , which measures the position and width of the sections, and the nested tabs.
The result was that a font of about 20 KB, needed only well below the fold, could be requested after just 640 milliseconds.
On the homepage, we've replaced much of the stretch JavaScript with CSS. Of the 18 sections that used it, measured on viewports between 1280 and 2560 pixels, 15 were already naturally as wide as the window.
The other three belonged to a template with a 1400 pixel container and could be extended with a simple rule based on width: 100vw e margin-left: calc(50% - 50vw), without the need for JavaScript calculations.
4. The halved document: inline SVGs
This was probably the most important lever of the entire work , and we would hardly have identified it without analyzing the HTML document practically byte by byte.
The mobile home weighed approximately 647 KB uncompressed and 128 KB compressed . Of this, approximately 71 KB compressed consisted of inline SVGs : 45 Elementor widget icons inserted directly into the document in full.
A single icon, derived from a vectorized logo with 83 paths, weighed approximately 100 KB uncompressed and 30 KB compressed . This is nearly a quarter of the entire compressed HTML document for an icon hidden inside a closed tab.
In the Lighthouse model, reducing the document size can also have a significant impact on rendering metrics. Lab testing, rewriting the document, showed a drop from about 91 points to 97-98 points and an improvement of around 0,7 seconds on FCP and LCP.
The final implementation uses a filter on the theme's output buffer:
- SVGs after the second top-level section remain in the document as elements
<svg>empty with the same attributes, thus maintaining boxes and dimensions; - drawings are moved to a page-specific, compressible, long-cached file;
- a script at the bottom of the body, when the icon approaches the window, downloads the file only once;
- the symbols are copied to a hidden SVG in the document and the individual icons are reconstructed via
<use>local.
In doing so, we also encountered three problems that illustrate the difference between a theoretically correct idea and a truly usable implementation.
The first concerns references to external SVG files: under certain conditions, Chrome may temporarily leave inserted icons blank while the file is still loading. Hence the decision to copy the symbols into the document.
The second concerns the collision of identifiers and classes. If two logos both use a class like .st0, one style can override the other. We have therefore introduced a specific prefix for each symbol.
The third concerns the severity of the XML parser: an attribute with an undeclared namespace can invalidate part of the file. SVGs are therefore normalized and validated before being extracted from the HTML.
The 100KB icon has also been replaced with the official vector of just 457 bytes.
The overall result is that the mobile home went from 128 KB to about 62 KB of compressed HTML.
5. Fonts: only what you need, when you need it
We also chose to intervene on the fonts only where the measurements showed a real benefit.
- We have removed the critical CSS from the 14 latin-ext faces of Open Sans that the site does not use.
- The Linux hero icon, which alone forced the browser to download about 10 KB of Font Awesome Brands before the LCP, has been converted to an inline SVG extracted from the font.
- The brand's font subsets were already sufficiently optimized: approximately 189 Latin glyphs in 22 KB. We checked them and left them unchanged.
- The preloads were reviewed one by one, keeping only those that produced a measurable benefit.
One case is particularly notable. Preloading a font used only below the fold, initially added to eliminate a dependency flagged by PSI, worsened the LCP by about 170 milliseconds in the lab.
It was then deleted. Having a seemingly cleaner dependency tree doesn't necessarily mean a faster page.
6. JavaScript: Defer what you have to, eliminate what you can
We haven't replicated a model that indiscriminately delays all JavaScript until the first user interaction. That type of solution can certainly improve some synthetic metrics, but it also risks leaving carousels, tabs, menus, and other components uninitialized for part of the experience.
We preferred to intervene selectively:
- jQuery Deferred, with a minimal shim for jQuery UI compatibility and a filter for inline plugin scripts that call jQuery synchronously;
- Removed wp-i18n and wp-hooks from frontend in places where they were not actually used;
- iubenda delayed through our own initialization logic;
- tooltips loaded on mouse approach;
- chat widgets loaded later;
- analytics initialized in compliance with consent.
The important point for us is that the actual page remains usable and consistent , without turning optimization into a simple exercise in reducing what Lighthouse can observe.
The final Total Blocking Time is generally between 3 and 50 milliseconds.
jQuery is still present. Elementor requires it, and with a TBT of this level, eliminating it at all costs would not have produced a proportionate benefit. Removing it would actually mean completely rethinking the home page without Elementor: a different project,
7. The stack: microcache, one-time compression, and a years-old bug
A significant part of the work was also done under WordPress, because real performance does not end with HTML, CSS and JavaScript.
An nginx microcache in front of Varnish
We introduced an nginx microcache in front of Varnish , not so much to further improve the speed of the HIT caches, on which Varnish was already responding in the millisecond range, but to increase the resilience of the entire stack and better absorb any spikes or anomalies in the underlying layer.
In practice, nginx represents a very lightweight layer in front of Varnish, capable of immediately serving an already available copy without having to re-involve the entire application chain. The main advantage is not squeezing a few milliseconds out of an already fast response, but reducing the number of requests that actually have to reach Varnish, the nginx backend, PHP-FPM, and WordPress when not needed.
The configuration also allows objects to be updated in the background while still serving the current copy, and to use a previous copy in the event of a temporary backend failure. This means that a slowdown, timeout, or brief application issue doesn't necessarily have to result in a user-perceived error: if a valid or usable copy still exists in the cache, nginx can continue serving it while the underlying layer recovers.
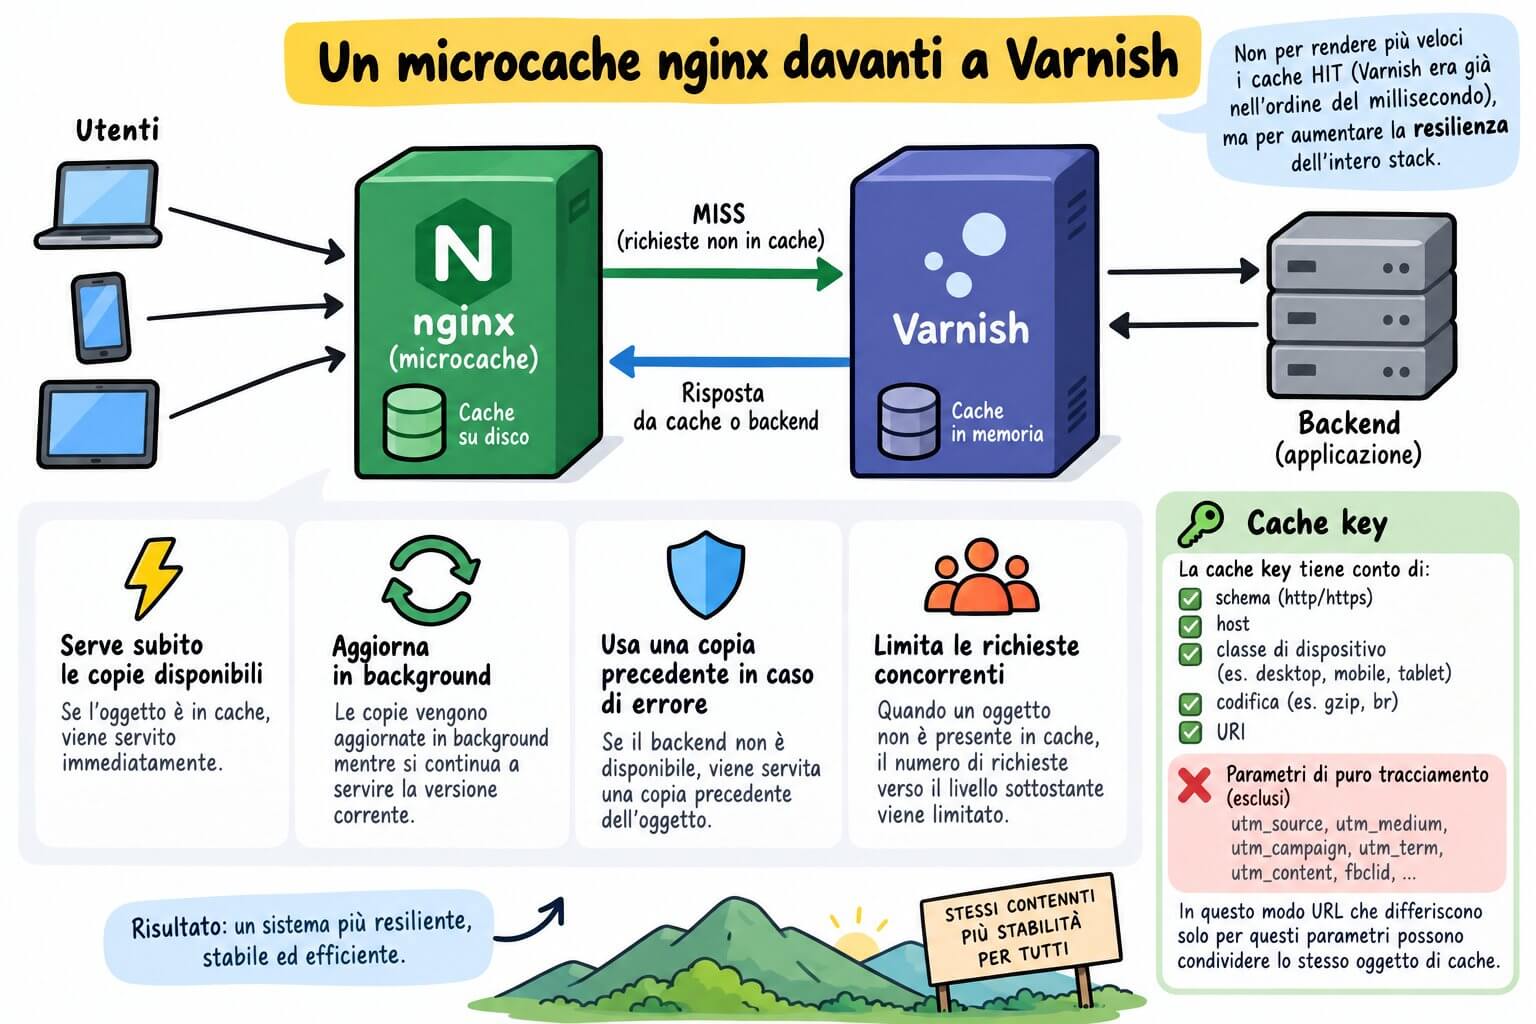
Another important aspect is controlling concurrent requests in the event of a cache miss. When an object is not present in the cache, instead of allowing dozens of simultaneous requests for the same URL to traverse the stack at once, it is possible to ensure that only one request updates the copy while the others wait or use the one already available . This is a particularly useful measure during traffic spikes or immediately after a cache flush, as it avoids the classic "thundering herd" effect on the backend.
Also the cache key It has been carefully constructed. It takes into account scheme, host, device class, encoding, and URI, while parameters used exclusively for tracking are excluded. This allows URLs that differ only in parameters such as utm_source, utm_medium, utm_campaign o fbclid can share the same cache object.
It's a less trivial detail than it seems: without this normalization, the same page could end up in the cache multiple times simply because it was reached by different campaigns, social networks, or sources. Eliminating from the cache anything that doesn't actually modify the content therefore allows you to increase the HIT rate, reduce memory waste, and further limit the work required by the backend.
The result is a cache layer that serves not so much to make a response already present in Varnish “faster than fast,” but to make the entire architecture more stable, predictable, and error-resistant.
Compression moved to the backend
Previously, the frontend would recompress responses even when they came from cache, spending about 30-40 milliseconds of CPU time on HTML and CSS.
We've moved compression to the backend, so it's done only once per page and per encoding. Varnish and NGINX can then store and serve the already compressed variants directly, using the correct Vary: Accept-Encoding.
In our case we had to take into account a specific behavior of the parameter http_gzip_support, which can interfere with the handling of different encodings towards the backend.
Compression levels chosen on the numbers
For HTML we chose Brotli 9 and Zstandard 15. Going further significantly increases the CPU cost at the expense of a reduction in bytes which, in our tests, did not justify the increased time spent on a MISS cache.
For files produced by Autoptimize, which contain the content hash in the name and can therefore remain cached for a long time, we use more aggressive levels: Brotli 11 and Zstandard 19.
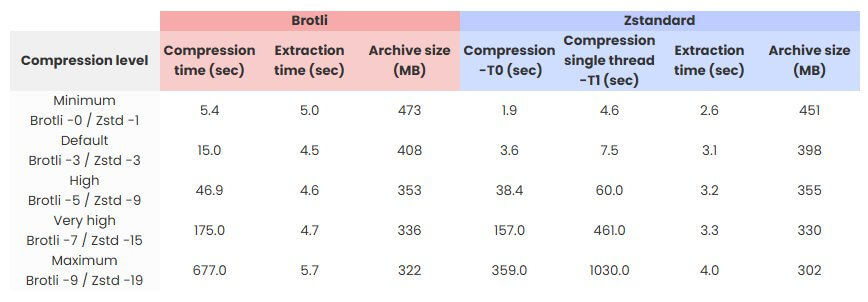
In this second case, incurring a higher CPU cost only once has a decidedly better cost-benefit ratio.
The bug that explained the hanging requests
During our warmup procedures, we noticed that about 1,5% of requests could remain unanswered for periods of between 120 and 300 seconds , apparently to random URLs.
PHP wasn't showing up in the slow request logs, so we continued down the stack.
We found thousands of errors in Varnish's ring buffer http first read error: -1 11.
The cause was the reuse of keepalive connections that the nginx backend had already closed after the period of inactivity. Varnish then attempted to write a new request to a now dead socket, waiting for the first_byte_timeout and could subsequently go through multiple restarts defined by the VCL.
The fix was simple: keepalive_timeout 0 on the backend. Each fetch opens a new connection on the loopback, with negligible cost in our scenario, but eliminating the race condition.
We then verified the solution by exactly reproducing the time window that was causing the problem: zero errors.
The little things you discover just by looking
During the analysis we also found less spectacular, but still worthy of being fixed, problems:
- The MIME type of WOFF2 files was
application/octet-stream; - some static files came out with two headers
Cache-Control; - Varnish's storage was limited to 512 MB, while the site, considering three encodings and two device classes, could occupy approximately 520 MB.
Varnish's storage has then been bumped up to 2GB of RAM.
8. The warmup with three encodings
When the cache keeps a separate copy per encoding, a warmup that requests each URL only once warms up only one of the possible variations.
We then rewrote our script starting from the sitemap:
- GET requests and not HEAD;
- three requests per URL with gzip, Brotli and Zstandard;
- mobile and desktop user-agent;
- one controlled process at a time;
- Configurable pause between requests to avoid unnecessarily saturating PHP-FPM on a completely empty cache.
The full site warmup involved 781 URLs, two devices, and three encodings , for a total of 4.386 requests.
The process took about three and a quarter hours, never exceeding an average load of 1. On sample URLs checked subsequently, we obtained 24 out of 24 HITs , with times ranging from 22 to 48 milliseconds.
What we didn't do, and why
Being honest about the limitations of an intervention is as important as listing the results achieved.
- We have not definitively identified the cause of the “slow mode” of the first frame in the lab. In some Lighthouse rounds, the main thread appears to have painted the page well before the compositor actually displays the frame. We tried several variations of the homepage by removing scripts, videos,
content-visibility, external sheets, preloads, and section groups, without being able to isolate a single culprit. The behavior is unobservable in the field data, so we documented the phenomenon and decided not to pursue it further. - We did not regenerate a critical CSS limited to the first fold only. Going from about 57 KB uncompressed to 35 KB produced only a few tens of milliseconds of improvement in the lab, but introduced the risk of seeing the second section settle during loading.
- We didn't clip all the deferred CSS per page. On the home page, a very significant portion of the full spreadsheet is unused, but building page-specific deferred CSS with Elementor would introduce significant fragility with every change made from the editor.
- A pre-existing CLS remains on a pricing page. This is due to the font swap on some large text blocks and will require a fallback font with aligned metrics. This is a separate fix that can be applied systematically across the site.
The results
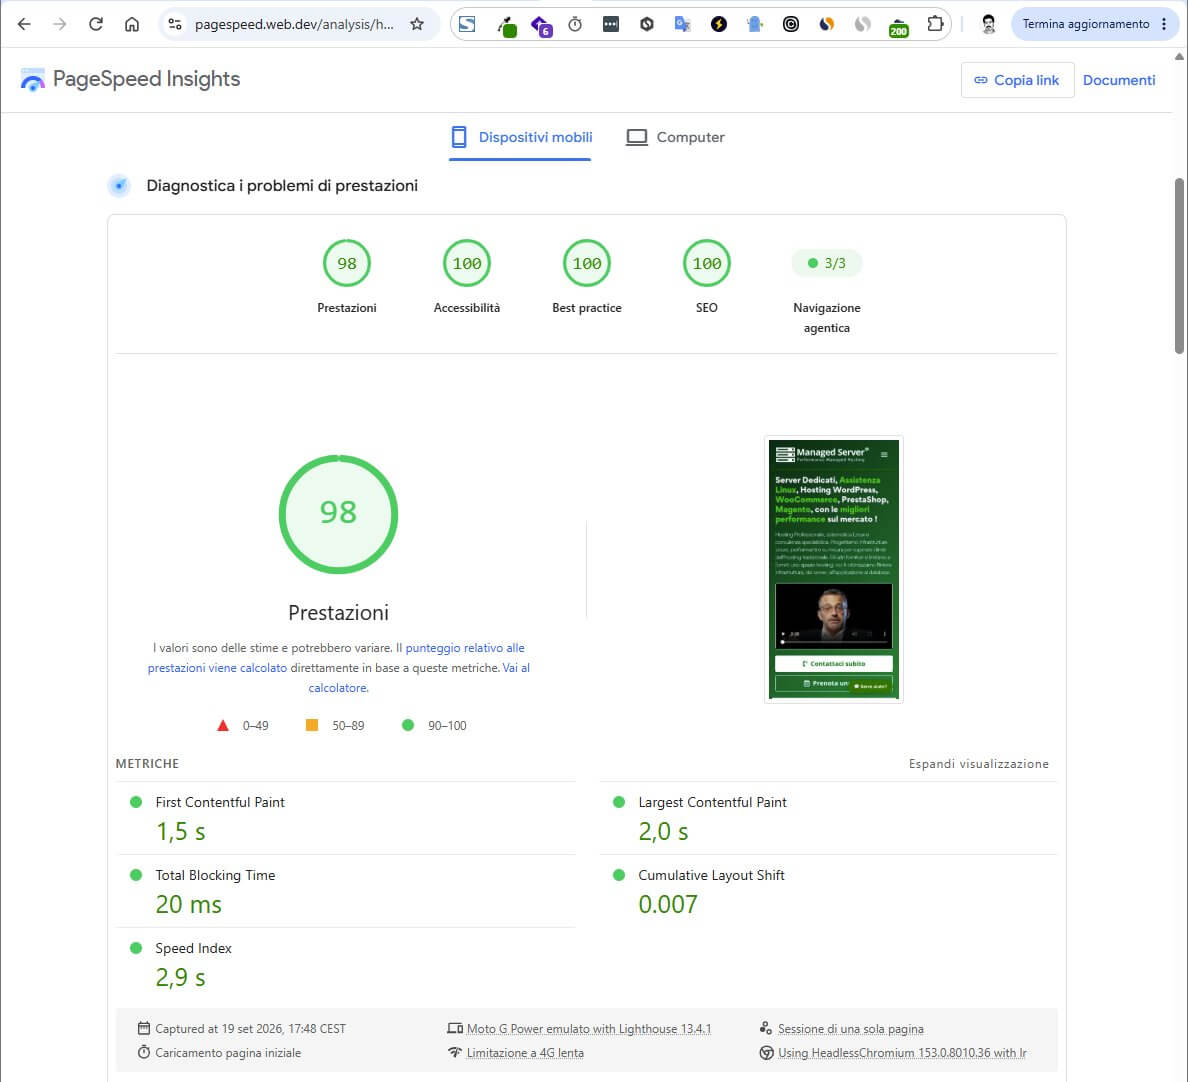
On the mobile home, after the interventions, three separate analyses carried out in the same session showed significantly better results than the configuration without Nitropack.
| Metric | First, without Nitropack | After |
|---|---|---|
| Mobile Score | 76-86 | 98 |
| First contentful paint | 2,0-2,4 p | 1,5 s |
| Largest Contentful Paint | 3,8-5,3 p | 2,3 s |
| Speed Index | 3,3-5,0 p | 1,5-1,8 p |
| Total Blocking Time | 0-100 ms | 3-50 ms |
| Cumulative Layout Shift | 0 | 0 |
| LCP rendering delay | 1.050-2.112 ms | 130 ms |
| Compressed HTML document | 128 KB | 62 KB |
On desktop we reached 100 points.
The field data has remained green, as it was before. The difference is that today we have a lighter front end, a more predictable stack, and above all, we know exactly where the bottlenecks have been eliminated and why each intervention produces a benefit.
The homepage also transfers about 60 KB less compressed HTML . On a slow mobile connection, this is not just a cosmetic score improvement; these are bytes the user doesn't actually need to download.
And the Nitropack subscription was not renewed.
How much work does this kind of optimization really require?
Finally, there is one aspect that is worth clarifying, especially because from the outside, work of this type can easily be confused with the installation of a caching plugin or with a few changes made in an afternoon.
In our case, we spent about 20 full hours of actual technical work , distributed between measurements, trace analysis, solution development, testing, benchmarking, frontend changes, nginx/Varnish stack interventions, debugging, and final checks.
These aren't 20 hours spent randomly experimenting with PageSpeed Insights. They're hours of specialized work that require simultaneous expertise in browser performance, WordPress, Elementor, CSS, JavaScript, nginx, Varnish, HTTP caching, compression, and system analysis.
And it is also important to assign a realistic value to this type of intervention.
Considering an average market rate of around 80 euros per hour for specialized technical activities of this level, an equivalent job could hardly be sold for less than 1.600 euros + VAT.
The calculation is extremely simple: 20 hours × €80/hour = €1.600 + VAT.
This also helps explain why it doesn't make much sense to directly compare true manual optimization with the monthly or annual cost of an automatic service. They're two different products.
An automated service can be cost-effective because it applies standardized logic to thousands of sites, producing a cosmetic effect and a cheating green score that provides no real value to the visitor. A manual intervention, on the other hand, means analyzing that specific site, understanding where bytes and milliseconds are actually being spent, modifying the code and infrastructure, verifying the side effects, and deliberately choosing which optimizations not to make.
In our case, the result isn't just a higher PageSpeed score. We also benefit from all the infrastructure changes, the critical CSS of the pages, the new SVG system, the font optimizations, the caching logic, the compression management, the new warmup, and above all, the technical knowledge gained on this specific site during the tailored optimization process.
This is the difference between buying a score and buying – or doing internally – performance engineering work.
What we take home
- A good score should represent a really fast site. If a technique only improves what the tester sees but doesn't reduce the work the visitor has to do, it's worth asking whether you're optimizing the site or just the measurement.
- The size of your HTML document matters a lot. Before focusing solely on JavaScript and fonts, it's a good idea to measure the document as well. In our case, a huge portion of the HTML consisted simply of inline SVG icons.
- Each intervention must be measured several times. We discarded several seemingly obvious optimizations because the numbers showed an unfavorable cost-benefit ratio.
- The stack matters as much as the frontend. A keepalive issue between Varnish and nginx had been causing random timeouts for a long time. No WordPress optimization plugin could have detected it, because the problem was on a completely different level.
- True optimization requires cross-functional skills. Frontend, browser, web server, cache, compression, PHP and WordPress cannot always be treated as separate compartments by either the system administrator or the web developer.
- It takes time. In our case it took about 20 full hours of technical work. Valued at an average market rate of €80/hour they are equivalent to at least 1.600 € + VAT of professional activity. Not because the result necessarily has to be expensive, but because behind real optimization there are analyses, skills, tests, and responsibilities that an "Optimize" button cannot replace.
In the end, we achieved what we were looking for: we eliminated an external subscription service, really lightened the site, improved the lab metrics and made the underlying infrastructure more robust.
And most importantly, today when PageSpeed Insights returns 98 on mobile and 100 on desktop, we know exactly where those numbers are coming from and that they are real numbers and not fake ones obtained by cheating.
They are not the result of a shortcut.
They are the result of a site that we have measured, analyzed and optimized piece by piece, the awareness that no matter how much we optimize the server side, there will always be ample room for optimization on the HTML / CSS and JS application side and that each case is a case in itself to be solved in a tailored way.

