
Table of contents of the article:
In the HTTP world, we've been accustomed for decades to thinking about a few fundamental methods: GET to retrieve a resource, POST to send data to the server, PUT to update, DELETE to delete. This seemingly simple grammar underpins a huge portion of the modern web: websites, REST APIs, mobile applications, SaaS services, microservices, reverse proxies, CDNs, and caching systems.
As applications have evolved, however, an increasingly obvious gray area has emerged: how to properly handle complex read-only queries ? Consider a search with many filters, a GraphQL request, a reporting endpoint, a query with pagination, sorting, time ranges, and nested conditions. Semantically, the operation is a read: the server must return data, not modify it. So it would be natural to use GET. But from a practical standpoint, GET forces you to put everything in the URL, resulting in length limitations, encoding issues, poor readability, and potential privacy implications for logs.
For years, the most common solution was to use POST even for operations that were actually simple queries. POST allows you to send a structured body, such as JSON, but it conveys a different meaning to the protocol: a request that could change the server's state. This detail isn't just theoretical. For caches, proxies, CDNs, WAFs, and HTTP clients, the method used is crucial information. Using POST to read data often means giving up some of the optimizations HTTP already provides.
The new HTTP QUERY method , standardized with RFC 10008, was created precisely to fill this gap: it allows you to send a request with a body, like POST, but retains the properties of a read-only request, like GET. In other words, QUERY tells the server and intermediaries: "I'm executing a query, I can have a body, but I'm not asking to change the state of the resource."
The historical problem: GET is correct, but often insufficient
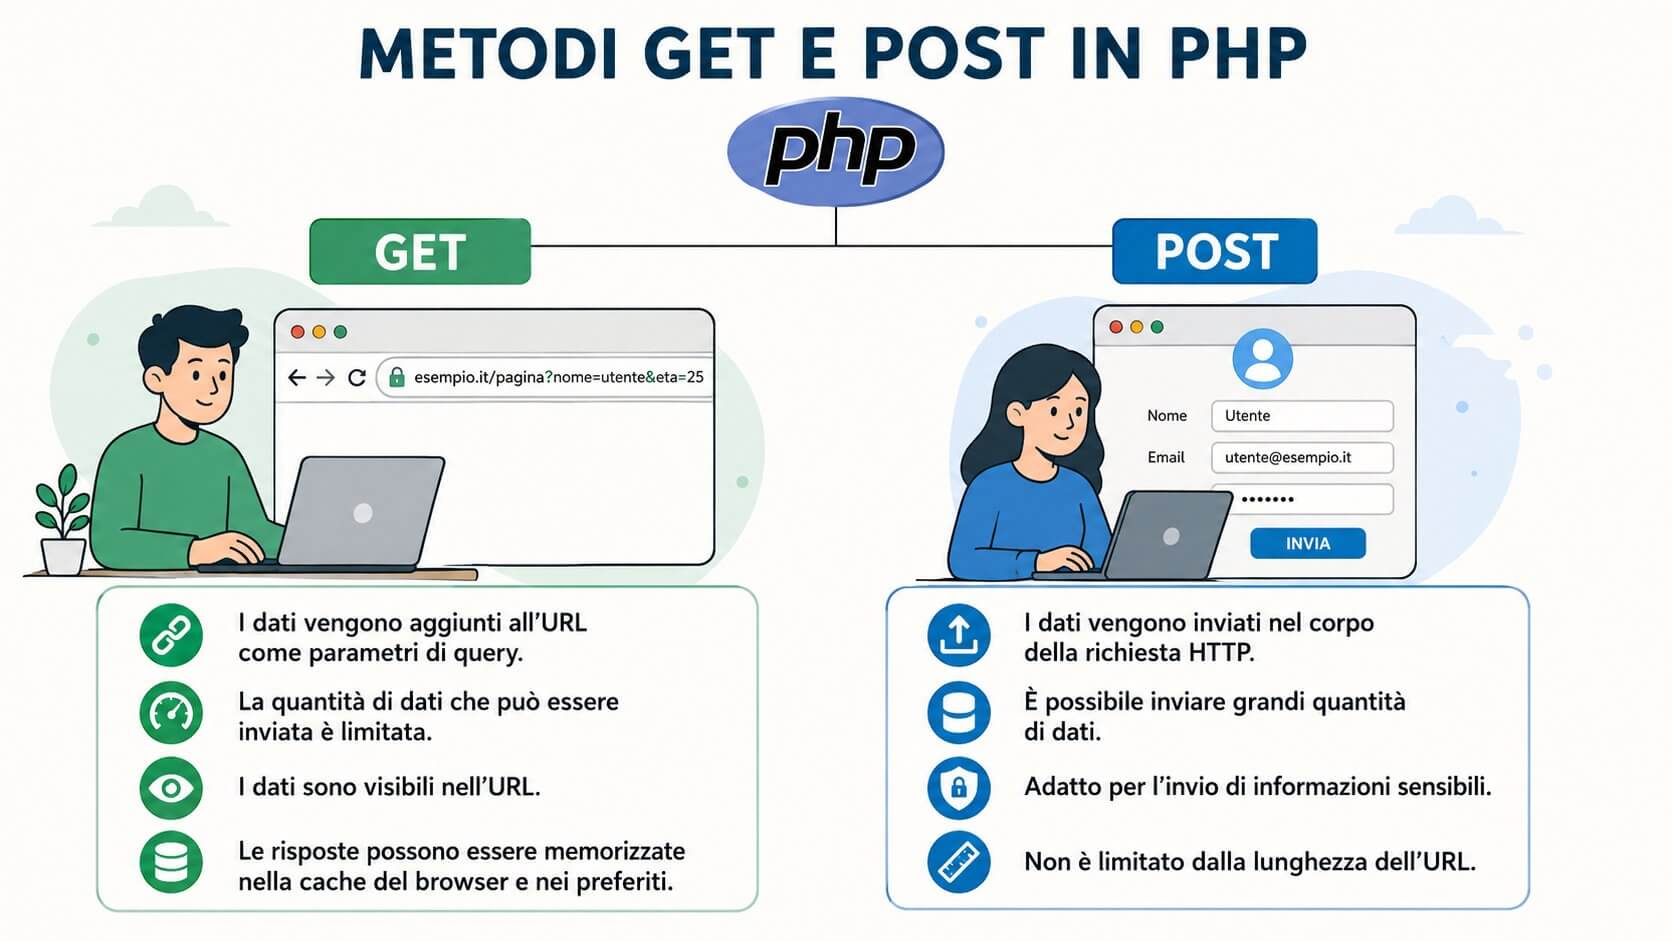
GET is the most natural HTTP method when we want to retrieve information. It's secure because the client doesn't ask the server to change the state of the resource, and it's idempotent because repeating the same request multiple times shouldn't produce different side effects. Furthermore, GET responses are easily handled by caches, browsers, reverse proxies, and CDNs.
The problem arises when the query becomes too complex. A request like this is perfectly manageable:
GET /prodotti?categoria=hosting&limit=10&sort=prezzo HTTP/1.1
Host: example.com
But what happens when you have dozens of filters, perhaps with nested conditions, arrays, dates, logical operators, full-text search, sorting preferences, and aggregation parameters? The URL becomes long, difficult to read, and more fragile throughout the delivery chain. Browsers, client libraries, enterprise proxies, load balancers, CDNs, and application firewalls can have different limitations and behaviors.
Then there's an often overlooked issue: URLs are very easily logged . They end up in web server logs, reverse proxy logs, browser history, analytics tools, monitoring systems, or debugging dashboards. If the query contains sensitive data, even indirectly, including it in the query string isn't always the most prudent choice.
Why POST has never been an elegant solution
POST solves the practical problem of the body. We can send complex JSON, a GraphQL query, an XML payload, or a custom application format without having to compress everything into the URL. For this reason, many modern APIs have used POST even for read-only operations.
The point is that POST doesn't convey the same semantics to the protocol as GET. A POST can create a resource, update a state, start a process, record an order, send a message, and produce permanent effects. When we use it simply to query data, the server knows this, the application client may know it, but HTTP intermediaries can't generally deduce it.
This means that caching, automatic retry, proxy optimizations, and CDN strategies become more complicated. An intermediate system can't assume that repeating a POST is harmless. It can't treat it with the same ease as a GET. As a result, many APIs that perform heavy reads end up always burdening the backend, even when the response would technically be reusable.
What does HTTP QUERY introduce?
QUERY introduces a simple but very powerful concept: a request can have a body, but remain read-only. The structure is similar to POST, but the semantics are different.
QUERY /api/search HTTP/1.1
Host: example.com
Content-Type: application/json
Accept: application/json

{
"q": "hosting linux managed",
"limit": 20,
"sort": "-created_at",
"filters": {
"status": "active",
"type": ["article", "service"]
}
}
With QUERY, the request content describes how to query the target resource . The server processes the query and returns the result, without the client requesting a change in the resource's state. The RFC defines QUERY as a secure and idempotent method: two crucial properties for those designing APIs that are reliable, scalable, and can be properly integrated with the HTTP infrastructure.
However, QUERY should not be confused with a new data format. QUERY does not impose JSON, SQL, GraphQL, or JSONPath. The format is declared via Content-Type . This makes the method flexible: each application can choose the most suitable query language, as long as the client and server agree on the meaning of the payload.
GET, POST, and QUERY Compared
| Property | GET | POST | QUERY |
|---|---|---|---|
| Sure | Yes | Not necessarily | Yes |
| Idempotent | Yes | Not necessarily | Yes |
| Body in the request | No general semantics defined | Yes | Yes |
| Suitable for complex queries | Only within certain practical limits | Yes, but with ambiguous semantics | Yes, with correct semantics |
| Cacheable | Yes | With strong practical limitations | Yes |
The main difference is precisely this: QUERY combines the body of POST with the semantics of GET . It may seem like a subtle detail, but for those working on high-traffic APIs, microservices architectures, or distributed infrastructures, it can make a big difference.
The role of the Accept-Query header
The RFC also introduces the Accept-Query header , designed to allow a resource to declare which query formats it supports. This is a useful discovery mechanism because it eliminates the client's guesswork.
HTTP/1.1 200 OK
Allow: GET, QUERY
Accept-Query: application/json, application/graphql
In this example, the server declares that the resource accepts QUERY requests with JSON or GraphQL payloads. For a well-designed client, this information is invaluable: it allows it to choose the correct format, handle fallbacks, and produce clearer errors when the format is not supported.
The presence of Accept-Query is also interesting from an infrastructure perspective. In an environment consisting of API gateways, reverse proxies, and backend services, being able to explicitly declare support for query formats helps design cleaner contracts between the various components.
Cache and reverse proxy: where QUERY gets really interesting
The practical value of QUERY comes into its own when we talk about caching. A GET request is normally identified by its URI. With QUERY, however, a cache must also consider the content of the request and relevant metadata, such as Content-Type and other headers that influence the result.
This allows for multiple cacheable responses on the same endpoint, distinguishing them based on the query body. Two identical QUERY requests can be served from the cache; two different QUERY requests to the same endpoint must produce different cache keys.
For a modern infrastructure, this opens up interesting scenarios:
- application load reduction on research or reporting endpoints;
- better exploitation of reverse proxies and CDNs in front of read-only APIs;
- safer retries in case of temporary network errors;
- clearer semantics between client, gateway and backend.
Of course, simply having a standardized method isn't enough for everything to work immediately. Every element in the chain must recognize it, or at least forward it correctly: web servers, proxies, load balancers, CDNs, WAFs, application frameworks, and client libraries.
Beware of adoption: standardization does not mean immediate support
An important point is to distinguish between standardization and actual adoption . Just because QUERY has been defined as an RFC and registered by IANA doesn't mean every browser, framework, CDN, or firewall already handles it optimally.
In real-world infrastructures, there are often explicit rules about permitted HTTP methods. A WAF might only allow GET, POST, HEAD, OPTIONS, PUT, and DELETE. A reverse proxy might have restrictive configurations. A legacy application might respond with an error to an unknown method. A logging system might not correctly classify the new request.
For this reason, QUERY should be considered a technology that should be carefully evaluated, especially in controlled contexts: server-to-server communications, internal APIs, test environments, microservices under the same operating domain, high-traffic search endpoints where clients and servers are managed by the same organization.
What this means for those managing hosting, Linux servers, and production APIs
From a systems perspective, QUERY isn't just a new feature for developers. It's a change that also affects those managing the infrastructure. If an application starts using QUERY, it's important to ensure that the entire chain is ready to receive and correctly forward the new method.
In a Linux environment with web servers, reverse proxies, and application firewalls, the main checks involve at least these aspects: Nginx or Apache configurations, WAF rules, CORS policies, logging, metrics, APM systems, load balancers, CDNs, and security tools. An unknown or not explicitly permitted HTTP method can be blocked before it even reaches the application.
It's also important to think about caching. If a reverse proxy or CDN starts caching QUERY responses, the cache key must include the request content and the correct metadata. Incorrect normalization could return incorrect results. Conversely, an overly conservative configuration could negate the benefits of the new method.
In other words, QUERY can be very useful, but it must be part of a thoughtful infrastructure design. It's not a simple "verb change" on the code side: it requires testing, observability, and consistent rules across the entire platform.
A practical example with curl
A client might send a QUERY request like this:
curl -X QUERY "https://api.example.com/search"
-H "Content-Type: application/json"
-H "Accept: application/json"
--data '{
"q": "server managed linux",
"limit": 10,
"sort": "-published_at"
}'
From an application perspective, the server receives a structured payload. Semantically, however, the request isn't a generic POST: it's a secure and idempotent query. This is the core of the standard.
Will QUERY replace GET or POST?
No. QUERY wasn't created to replace GET or POST, but to address a use case that until now has been handled with compromises. GET remains perfect for simple requests, resources directly identifiable by URL, and easily cacheable content. POST remains the correct method when the client sends data that can create, modify, or trigger processing that impacts the server.
QUERY fits in between the two: it's suitable when we need to execute a complex, read-only query with a body . It's therefore particularly interesting for search APIs, GraphQL, analytics endpoints, reporting, aggregations, and internal services that query large amounts of data without modifying it.
Conclusion
HTTP QUERY is an important new feature because it corrects a practical flaw that developers know well: using GET when the query doesn't fit comfortably within the URL, or using POST when it loses semantic clarity and infrastructure benefits. With QUERY, HTTP finally offers a method designed for complex, secure, idempotent, and cacheable queries.
For API developers, this means being able to design more consistent endpoints. For those managing Linux infrastructures, reverse proxies, CDNs, and managed environments, this means preparing to support a new HTTP method with appropriate configurations, tests, and policies.
As is often the case with standards, the impact won't be immediate. Adoption will require time, updates, and compatibility along the entire chain. But the direction is clear: QUERY makes HTTP more expressive, more correct, and better suited to modern APIs.
At Managed Server, we closely monitor these developments because they directly impact the performance, security, caching, and reliability of web applications. A well-managed infrastructure doesn't just run a website or API: it must also be ready to securely and confidently adopt the standards that improve the web.

