

Table of contents of the article:
It all started with a seemingly simple ticket.
A customer reported to us that downloading some large archives from their site was inexplicably slow when done via a browser.
This was not a marginal difference, one that can easily be attributed to normal network variability.
The same static archive, about 144 MB, downloaded from the client desktop application in about 17 seconds, while Chrome could take over 90 seconds.
On the one hand, we had a throughput in the order of 8-9 MB/s.
On the other hand just 1,5-2 MB/s.
The server, like many of our customers, was hosted at Hetzner, Germany, and was running NGINX with HTTP/2 and HTTP/3 enabled.
The first thought, faced with such a difference, is almost inevitably turned to the internet.
MTU?
Path MTU Discovery?
Packet loss?
Firewall?
UDP filtering?
Routing?
A datacenter infrastructure problem?
Some form of rate limiting?
A browser bug?
All absolutely plausible hypotheses.
The detail that made the case particularly interesting, however, was another: the client's desktop application used HTTP/1.1 over TCP, while Chrome, finding HTTP/3 advertised by the server, used QUIC over UDP.
The question then became much more specific:
Was it really the HTTP/3 protocol that made the transfer almost ten times slower?
To answer this question, we had to stop comparing different applications and isolate a single variable.
The customer, fortunately, had already done exactly that.
The customer had already isolated HTTP/2 from HTTP/3
The initial comparison between the desktop app and Chrome was interesting, but not yet sufficient to make a diagnosis.
Comparing two different applications in fact means introducing a lot of variables.
Your Node.js application may use different buffers, different TLS libraries, different connection management strategies, and even different download mechanisms than Chrome.
The truly meaningful test was to use:
- the same client;
- the same computer;
- the same Internet connection;
- the same binary as Chrome;
- the same hostname;
- the same server;
- the same file;
- the same HTTPS endpoint.
Only the protocol needed to change.
In the examples in this article, to ensure our client's privacy, we will anonymize the original domain using:
example.com
and we will call the file:
example-package-0.2.3-win-x64.zip
The URL used for benchmarks then becomes:
https://example.com/downloads/example-package-0.2.3-win-x64.zip
The important thing is that it was a completely static file served directly by NGINX.
No PHP.
No PHP-FPM.
No WordPress.
No database.
No proxy to a backend.
No application code.
This feature would become fundamental because it allowed us to immediately exclude a huge number of potential bottlenecks.
First test: disable QUIC and use HTTP/2
Chrome and Chromium allow you to launch them with QUIC completely disabled.
The switch is:
--disable-quic
On Windows, for example:
"C:\Program Files\Google\Chrome\Application\chrome.exe" ^
--disable-quic ^
--user-data-dir="%TEMP%\chrome-h2-test" ^
"https://example.com/downloads/example-package-0.2.3-win-x64.zip"
The use of:
--user-data-dir
It is especially useful during this kind of benchmark.
Chrome tends to reuse processes and profiles that are already open. Starting a different temporary profile reduces interference from previous sessions, cache, Alt-Svc status, and existing connections.
On Linux the equivalent might be:
google-chrome
--disable-quic
--user-data-dir=/tmp/chrome-h2-test
"https://example.com/downloads/example-package-0.2.3-win-x64.zip"
With QUIC disabled, Chrome negotiated HTTP/2.
The results measured by the client were:
HTTP/2

7,65 MB/s
9,67 MB/s
Therefore, substantially consistent with the speed observed by the HTTP/1.1 client, which saturated the bandwidth of the consumer ADSL connection (for example, when working from home, we use a 100 Megabit Fastweb).
So far so good.
Second test: forcing HTTP/3 on Chrome itself
At this point the previous instance was closed and the same Chrome binary was launched again, this time forcing QUIC to the specific origin.
The switch used is:
--origin-to-force-quic-on=example.com:443
It is important to pay attention to the syntax.
Sometimes this parameter is represented informally in documentation or examples as:
--origin-to-force-quic-on=[example.com:443]
but square brackets normally indicate a placeholder and should not be passed literally.
The actual syntax is:
--origin-to-force-quic-on=example.com:443
To make the test even more explicit we can also use:
--enable-quic
obtaining:
"C:\Program Files\Google\Chrome\Application\chrome.exe" ^
--enable-quic ^
--origin-to-force-quic-on=example.com:443 ^
--user-data-dir="%TEMP%\chrome-h3-test" ^
"https://example.com/downloads/example-package-0.2.3-win-x64.zip"
On Linux:
google-chrome
--enable-quic
--origin-to-force-quic-on=example.com:443
--user-data-dir=/tmp/chrome-h3-test
"https://example.com/downloads/example-package-0.2.3-win-x64.zip"
Same computer.
Same Chrome.
Same server.
Same file.
Same connection.
This time, however, the results were very different and much worse:
HTTP/3

1,64 MB/s
1,95 MB/s
A huge difference, from 10 Megabytes per second (which would certainly have increased with a faster ADSL or fiber connection) to a connection throttled to less than 2 Megabytes per second.
The decisive test: H2 → H3 → H2
The client had also done something else that was methodologically very correct.
The tests were not run in two separate blocks, for example ten HTTP/2 benchmarks in the morning and ten HTTP/3 benchmarks half an hour later.
They had been intertwined.
The sequence was:
HTTP/2
HTTP/3
HTTP/2
The results:
--disable-quic

HTTP/2
7,65 MB/s
9,67 MB/s
then:
--enable-quic
--origin-to-force-quic-on=example.com:443

HTTP/3
1,64 MB/s
1,95 MB/s
and immediately after:
--disable-quic

HTTP/2
7,55 MB/s
9,68 MB/s
In even more evident form:
HTTP/2    ~8-10 MB/s

HTTP/3    ~1,5-2 MB/s

HTTP/2    ~8-10 MB/s
This sequence was beginning to make the explanation based on generic Internet congestion less credible.
Indeed, one would have to assume that the connection suddenly became five or six times slower exactly when QUIC was activated, and then immediately became faster again when switching back to HTTP/2.
Possible in theory.
Very unlikely when the result is reproducible.
Check the protocol in Chrome DevTools
When running benchmarks of this type, however, it is important not to blindly trust the flags used to launch the browser.
Chrome DevTools allows you to view the protocol actually used.
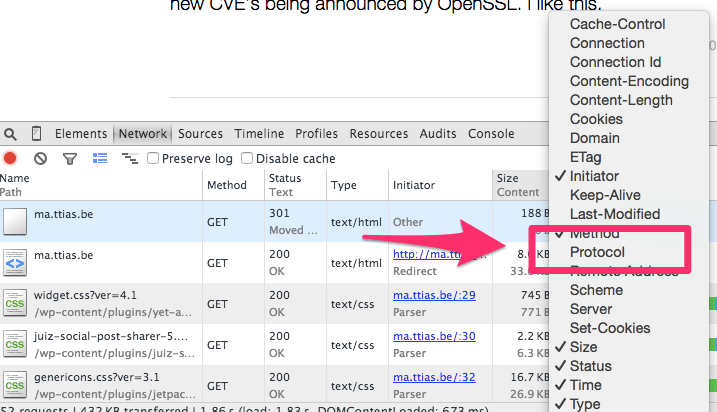
Just open:
F12
→ Network
and enable the column:
Protocol
In the first test it is necessary to check for the presence of:
h2
while in the second:
h3
This check prevents a request from being interpreted as HTTP/3 if, for whatever reason, it has fallen back to HTTP/2.
First hypothesis: a UDP problem on the Hetzner network?
HTTP/2 uses TCP.
HTTP/3 uses QUIC over UDP.
It was therefore natural to begin investigating everything that could penalize UDP while leaving TCP essentially unchanged.
The server was hosted on the Hetzner infrastructure in Germany, and we started to consider possible network path-specific behavior.
Among the first hypotheses:
- UDP packet loss;
- UDP filtering;
- UDP policing;
- different routing;
- intermediate firewall problems;
- different coding or shaping for UDP and TCP.
A small amount of packet loss can significantly impact congestion control.
HTTP/3 is not simply “HTTP/2 over UDP”: QUIC directly implements many features that traditionally belong to the TCP stack, including acknowledgements, congestion control, and retransmissions.
The behavior of a QUIC flow in the presence of loss can therefore be significantly different.
Second hypothesis: MTU and Path MTU Discovery
Next we considered one of the classic problems of UDP connections: the MTU.
A path with a smaller than expected MTU, an intermediate tunnel, or incorrect handling of ICMP Packet Too Big messages can cause behavior that is difficult to diagnose.
TCP has had a very mature ecosystem around MSS and Path MTU for decades.
QUIC must instead manage UDP datagrams and packetization according to its own dynamics.
They then became suspects:
MTU
PMTU
ICMP filtering
UDP fragmentation
tunnel
VLAN/VXLAN
During such a diagnosis it can be useful to directly observe the traffic:
tcpdump -ni any udp port 443
and compare it with:
tcpdump -ni any tcp port 443
But something was missing here too.
HTTP/3 throughput didn’t just seem “choppy.”
It almost seemed to stop systematically around a precise value.
Socket buffer and kernel UDP statistics
The search then continued in the Linux stack.
A high-performance HTTP/3 server also depends on proper UDP socket handling.
Among the first checks:
netstat -su
or:
nstat -az
looking for values such as:
UdpInErrors
UdpRcvbufErrors
UdpSndbufErrors
and then the kernel buffers:
sysctl net.core.rmem_max
sysctl net.core.wmem_max
sysctl net.core.rmem_default
sysctl net.core.wmem_default
All technically valid hypotheses.
But that number continued to be there.
About 1,6 MB/s.
The number that was starting to look too precise: 64 KB
During the analysis we started to look more closely at NGINX's HTTP/3 configuration.
There is a directive called:
http3_stream_buffer_size
The official documentation describes it as the size of the buffer used to read and write QUIC streams.
The default is:
http3_stream_buffer_size 64k;
and the directive can be set in the contexts:
http
server
The 64 KB value immediately became interesting.
An NGINX maintainer explained to us that NGINX limits the amount of unacknowledged bytes on a single HTTP/3 stream as a function of http3_stream_buffer_size.
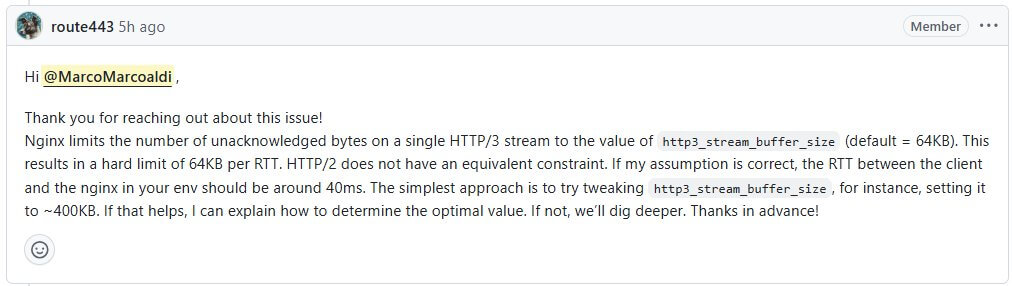
In practical terms this can translate, under certain conditions, into a limit of the order of:
buffer / RTT
Let's imagine an RTT of approximately:
40 ms
With the default buffer:
64 KB
we get:
64 KB / 0,040 s ≈ 1,6 MB/s
And it was exactly the order of magnitude of our benchmarks:
1,64 MB/s
1,95 MB/s
At that point the problem stopped seeming random.
The Bandwidth-Delay Product concept
The principle is the same that those who have been working with TCP for years know from the Bandwidth-Delay Product.
If we want to keep a certain amount of bandwidth constantly occupied, we need to have enough data “in flight” during the time it takes for the acknowledgements to return to the sender.
Let's say we want to achieve:
10 MB/s
with:
RTT = 40 ms
The BDP is:
10 MB/s × 0,040 s
or:
0,4 MB
about:
400 KB
A 64 KB buffer is therefore much smaller than the amount of data that would need to be able to remain in flight at one time to saturate that path.
It is no coincidence that the suggestion received was to try a value in the order of:
http3_stream_buffer_size 400k;
or, more conveniently:
http3_stream_buffer_size 512k;
To have margin we could use:
http3_stream_buffer_size 1m;
The importance of BDP in sizing windows and buffers over high-bandwidth, high-latency paths is not new: it is one of the fundamental principles of wide area network throughput.
There was also a curious detail in the technical documentation published by NGINX itself: in its QUIC performance benchmarks with high RTT and BDP, NGINX used:
http3_stream_buffer_size 50m;
so a value enormously higher than the default of 64 KB.
A problem already seen by others
In the meantime we had also found an extremely similar NGINX public issue, #1498 (https://github.com/nginx/nginx/issues/1498), a relatively recent and current issue considering that we are on September 1st 2026 and the issue was opened on June 23rd 2026, about 2 months ago.
In that case, a static 1GB file was served directly by NGINX.
The results were approximately:
HTTP/2    ~30 MB/s
HTTP/3    ~3,2 MB/s
Same server, same network path, no application upstream.
UDP, GSO, and other network aspects were also checked there, but no immediate explanation was found. The issue was being analyzed by the NGINX project.
The parallel with our case was evident.
Our relationship was about:
9 MB/s vs 1,8 MB/s
that of the issue:
30 MB/s vs 3,2 MB/s
It wasn't necessarily the same bug, but certainly the same class of phenomenon.
Let's change http3_stream_buffer_size
At that point it seemed like we had found the right path.
The main virtual host configuration contained, in simplified form:
server {
listen 192.0.2.10:443 quic reuseport;
listen 192.0.2.10:443 ssl http2;

```
server_name example.com;

...

quic_gso on;
http3_stream_buffer_size 16m;

...
```

}
We had intentionally used:
16m
a value that is enormously higher than the 400-500 KB theoretically required.
Not because 16MB was the right value to use in production, but because we wanted a near-binary test.
If the problem was the buffer, going from:
64 KB
a:
16 MB
the change should have been evident.
We performed:
nginx -t
followed by the reload.
New benchmark.
HTTP/3 continued to run at pretty much the same speed.
About ten times slower than HTTP/2.
It seemed that the hypothesis was wrong.
And yet it was precisely at that moment that the case became more interesting.
Why 16m didn't anything change?
The configuration contained two HTTPS virtual hosts on the same IP:port pair.
In extremely simplified form:
server {
listen 192.0.2.10:443 quic;
listen 192.0.2.10:443 ssl http2;

```
server_name www.example.com;

...
```

}
and subsequently:
server {
listen 192.0.2.10:443 quic reuseport;
listen 192.0.2.10:443 ssl http2;

```
server_name example.com;

http3_stream_buffer_size 16m;

...
```

}
The directive:
http3_stream_buffer_size 16m;
was present exclusively in the second server {}.
Normally, when thinking in terms of traditional HTTP and virtual hosting, it comes naturally to think:
The request comes for
example.com, then NGINX selects the server block ofexample.comand uses its parameters.
But QUIC introduces a timing problem.
The connection must be initialized before a normal, fully processed HTTP request can exist.
And this is where we decided to stop thinking only about the documentation and go directly to read the NGINX source code.
Reading the NGINX Source: Where the HTTP/3 Connection Really Starts
The interesting feature is found in:
src/http/ngx_http_request.c
inside:
ngx_http_init_connection()
This is a very important feature because it represents one of the first points at which NGINX associates a new connection with the HTTP subsystem.
The code first determines the address and port configuration on which the connection arrived.
At one point we find a particularly significant line:
hc->conf_ctx = hc->addr_conf->default_server->ctx;
The immediately preceding comment in the NGINX source is equally explicit: the default server configuration for that address:port pair is used at this stage.
This means that, at that precise moment, NGINX has not yet started from the virtual host configuration that we intuitively associate with the requested name.
He is working with the context of:
default_server
associated with the listener.
So far this might not be a problem.
The crucial part comes a few instructions later.
In the same function we find the specific HTTP/3 management:
if (hc->addr_conf->quic) {
ngx_http_v3_init_stream(c);
return;
}
The logical sequence then becomes:
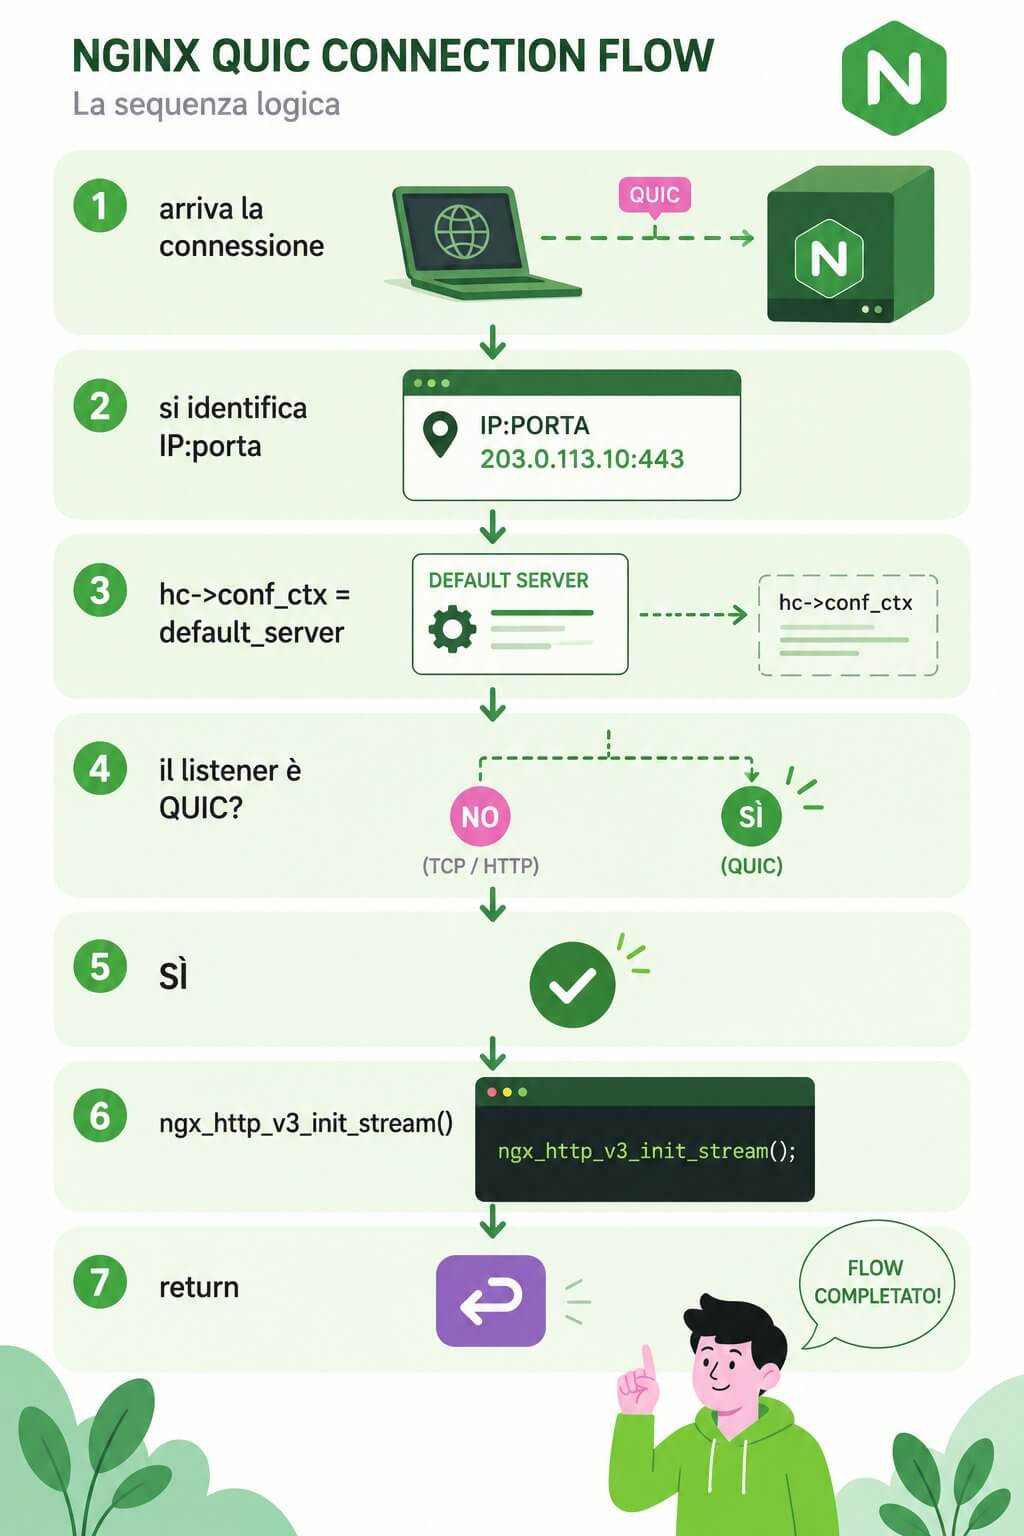
This return is particularly important.
NGINX does not proceed down the normal path of waiting for and parsing the HTTP request.
If the connection is QUIC, it immediately enters HTTP/3 initialization.
Let's go inside ngx_http_v3_init_stream()
At this point we followed the flow in the file:
src/http/v3/ngx_http_v3_request.c
The function:
ngx_http_v3_init_stream()
receives the newly initialized connection.
Inside we find another decisive passage:
h3scf = ngx_http_get_module_srv_conf(hc->conf_ctx,
ngx_http_v3_module);
and shortly after:
ngx_quic_run(c, &h3scf->quic);
Let's try to translate it without getting lost in the details of the NGINX internal API.
h3scf This is the server configuration of the HTTP/3 module.
Where is it recovered from?
From:
hc->conf_ctx
But a few moments before that hc->conf_ctx had been set to:
default_server->ctx
So the path becomes:
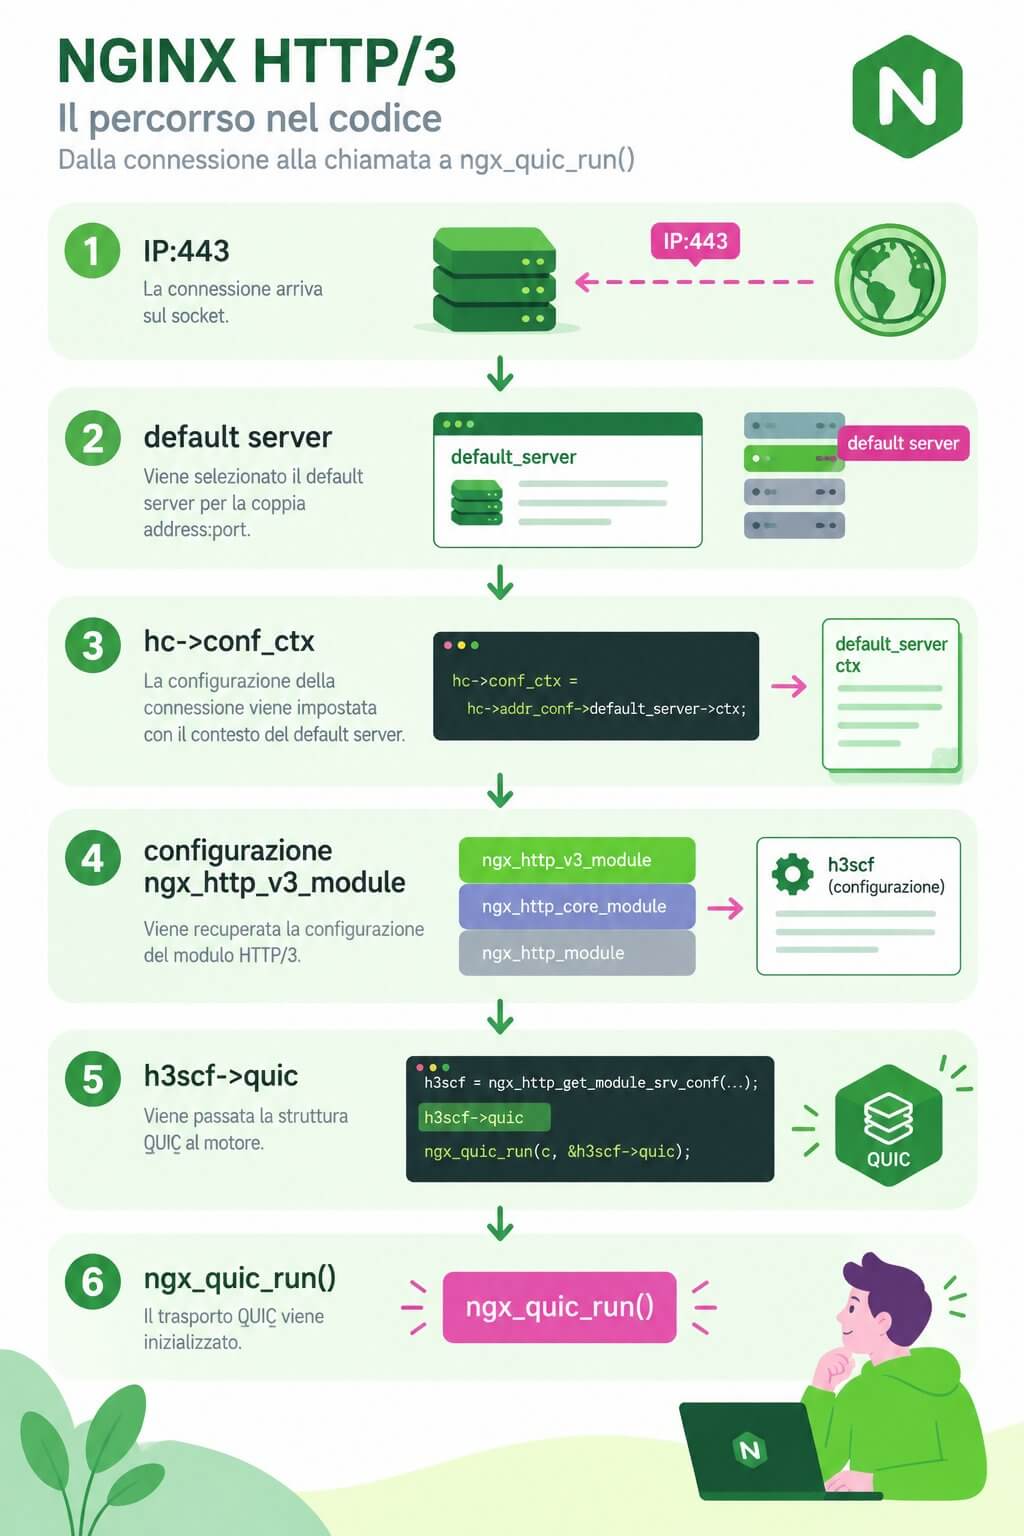
This is where our setup finally started to make sense.
The parameter:
http3_stream_buffer_size 16m;
was present in the second virtual host.
But the QUIC connection was initialized using the available context before the normal request-based HTTP virtual host selection.
The source also shows that, when child QUIC streams are subsequently created, NGINX may inherit the parent HTTP/3 connection context after the server name is handled; but at that point the initial QUIC transport has already been started via ngx_quic_run().
And this was exactly the detail we were looking for.
Let's dig even deeper: where is the 64 KB default defined?
At this point, one last check was missing.
Where it is actually set:
65536
as default?
The answer is in:
src/http/v3/ngx_http_v3_module.c
The directive's definition associates:
http3_stream_buffer_size
directly to:
quic.stream_buffer_size
within the HTTP/3 configuration.
When creating the configuration the value is initially marked as unset.
Next, in the configuration merge function, we find the value:
65536
as the final default.
Or:
65536 byte = 64 KiB
The source then confirmed exactly what the documentation reported:
http3_stream_buffer_size 64k;
But above all it showed that this value ended up directly in the structure:
quic.stream_buffer_size
which was subsequently switched to the QUIC engine.
We had finally reconstructed the entire route.
To put it very simply, the full path in the NGINX code is:
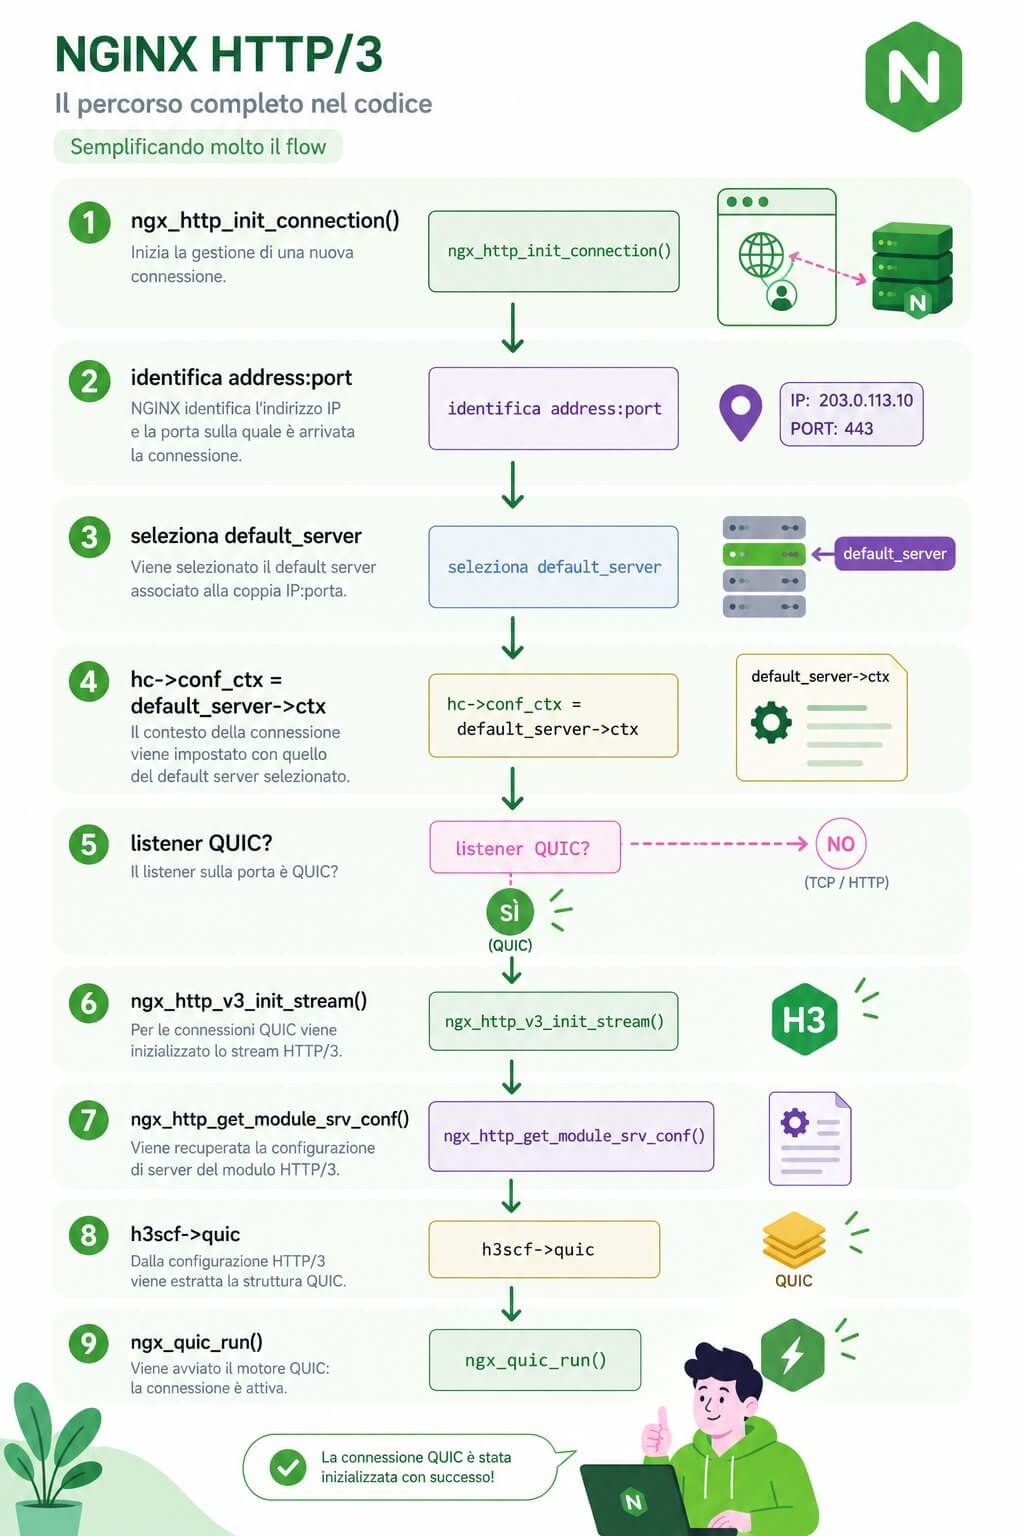
The important thing is not so much knowing these functions by heart.
It is understanding the temporal order of events.
With HTTP/3, we can't always think as if a normal, complete HTTP request arrives first and only then the entire virtual host is selected.
Some parameters needed for QUIC transport must be available much earlier.
The solution: move the parameter into context http
At this point we have modified the configuration.
Instead of having:
server {
server_name example.com;

```
http3_stream_buffer_size 16m;
```

}
we moved the parameter into the global block:
http {

```
http3_stream_buffer_size 1m;

...
```

}
The directive officially supports both contexts:
http
server
Use it at the level http {} However, it had one key advantage in our scenario: all virtual servers inherited the same value, and there was no longer any ambiguity during the QUIC initialization associated with the listener.
We verified the actual loaded configuration with:
nginx -T 2>&1 | grep -n http3_stream_buffer_size
so:
nginx -t
e:
systemctl reload nginx
New benchmark.
This time the result changed immediately.
HTTP/3 was no longer stuck at around 1,5-2 MB/s.
Throughput was comparable to that achieved through HTTP/2.
The problem was solved.
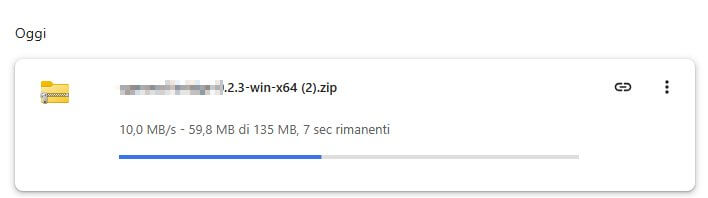
Even Chrome managed to saturate the connection of our 100 Megabit Fastweb connection.
Because the first change seemed correct but it wasn't
This is probably the most interesting part of the whole case.
The setup:
server {
server_name example.com;

```
http3_stream_buffer_size 16m;
```

}
it was not syntactically incorrect.
NGINX accepted it.
nginx -t returned correctly:
syntax is ok
test is successful
The directive is officially permitted in the context server.
Yet, in the particular topology with multiple QUIC virtual hosts on the same socket, it was not affecting the phase of the connection we were interested in.
So it wasn't a syntax error.
It was a misunderstanding of the connection lifecycle.
And this is exactly where reading the source code can make a difference.
Don't set 16MB for no reason
In our test we used:
http3_stream_buffer_size 16m;
solely as an experiment.
This does not mean that 16 MB is the optimal value.
The parameter should ideally be sized with respect to the bandwidth-delay product of the type of connections we want to serve.
With:
10 MB/s
40 ms RTT
we have:
10 × 0,040 = 0,4 MB
so about 400 KB.
A value like:
http3_stream_buffer_size 512k;
that might already be enough.
Or you can use a margin:
http3_stream_buffer_size 1m;
Of course, there is no universally correct number.
Let's consider for example a server that needs to support:
50 MB/s
towards client with:
80 ms RTT
The BDP becomes:
50 × 0,080 = 4 MB
In that case, a 512 KB buffer would again be insufficient to fully utilize the path.
The correct value therefore depends on:
throughput desiderato
×
RTT atteso
with an appropriate operating margin.
A practical diagnostic checklist
If you're faced with HTTP/3 being significantly slower than HTTP/2, I wouldn't start by changing ten parameters at once.
The sequence that this case suggested to us is more similar to the following.
First isolate the protocol:
H2 → H3 → H2
Then check that the file is really static.
Next check RTT:
ping example.com
and compare it to the observed throughput.
If, for example, you have:
RTT ≈ 40 ms
HTTP/3 ≈ 1,5 MB/s
The default 64KB immediately becomes suspect.
Then check:
http3_stream_buffer_size
and most importantly where it was configured.
With multiple QUIC virtual hosts on the same socket, check which one is the default server and seriously consider setting the shared QUIC parameters in context:
http {}
Only if the buffer does not change the behavior would I move on to the other possible hypotheses:
MTU / PMTU
UDP packet loss
firewall
UDP policing
routing
GSO
GRO
socket buffer
NIC
kernel
congestion control
This sequence avoids wasting hours on networking when the bottleneck is instead in the HTTP/3 transport configuration.
HTTP/3 is not automatically always faster than HTTP/2
One of the most common mistakes in web optimization is to associate the latest version of a protocol with an automatic performance boost.
HTTP/3 offers significant technological advantages.
QUIC avoids the transport-layer head-of-line blocking between streams typical of TCP, integrates secure transport with TLS, enables connection migration, and is designed with modern, mobile, and volatile networks in mind.
But none of these benefits mean:
HTTP/3 > HTTP/2
in every single benchmark.
The NGINX HTTP/3 module is still explicitly described in the official documentation as experimental , with the accompanying caveat emptor.
Furthermore, QUIC performance depends on elements that we could often ignore in the HTTP/2 world:
- buffer per stream;
- congestion control QUIC;
- RTT;
- packet loss;
- UDP offloading;
- kernel behavior;
- BDP sizing;
- server-specific implementation.
NGINX itself has published benchmarks in which tuning the QUIC congestion control produces very significant differences when varying RTT and BDP, using for those tests a http3_stream_buffer_size much higher than the default.
The value of debugging by exclusion
This case is also a good example of how a performance problem should be addressed.
At the beginning we had a very generic description:
“Files download slowly from the browser.”
A report like this could lead in dozens of directions.
The first major transformation was:
“Chrome is slow, the desktop app is not.”
Then:
“HTTP/1.1 and HTTP/2 are fast, HTTP/3 is slow.”
Then again:
“The file is static and the behavior follows the protocol exclusively.”
Finally:
“HTTP/3 throughput matches surprisingly well at 64 KB per RTT.”
Each test eliminated a piece of the problem.
It's the difference between randomly changing configurations and making diagnoses.
And above all: don't just trust the configuration we see
The second lesson is even more interesting.
We had set:
http3_stream_buffer_size 16m;
Looking at the virtual host everything seemed correct.
The requested domain was that one.
The directive was present.
NGINX had reloaded without errors.
But the result didn't change.
At that point we could have concluded:
"So
http3_stream_buffer_sizeit has nothing to do with it.”
It would have been a wrong conclusion.
Light:
src/http/ngx_http_request.c
e:
src/http/v3/ngx_http_v3_request.c
showed something that simply reading nginx.conf it doesn't make it obvious.
The sequence was:
default server del socket
↓
inizializzazione HTTP/3
↓
lettura della configurazione QUIC
↓
ngx_quic_run()
Only then do the additional mechanisms for associating the server name and streams fully come into play.
The problem was not that the value was too low.
It was that the value we thought we had changed was not the one used at the crucial moment of QUIC connection initialization.
The final configuration
In an infrastructure with multiple HTTP/3 virtual hosts on the same port, for parameters that we want to make common we therefore prefer a configuration like this:
http {

```
http3_stream_buffer_size 1m;

...

server {
    listen 192.0.2.10:443 quic reuseport;
    listen 192.0.2.10:443 ssl;

    server_name www.example.com;

    ...
}

server {
    listen 192.0.2.10:443 quic reuseport;
    listen 192.0.2.10:443 ssl;

    server_name example.com;

    ...
}
```

}
The value 1m It is only an example and must be sized according to the real case.
The key thing is that the parameter is consistently available at QUIC initialization time.
The same reasoning deserves attention for other QUIC server configuration directives, such as quic_gso, because in the source it is also stored in the QUIC configuration structure and the default is off.
This does not mean that every directive must be moved to the global block.
It does mean that when multiple virtual hosts share the same QUIC listener, you need to understand what information is needed during the very early stages of connecting.
Conclusions
We started with a customer who downloaded a static archive at about:
1,5-2 MB/s
with Chrome.
The same resource via HTTP/1.1 or HTTP/2 reached:
8-10 MB/s
We initially suspected:
MTU
PMTU
firewall
routing UDP
packet loss
socket buffer
GSO
NIC
kernel
Hetzner
All perfectly legitimate hypotheses.
The interlaced test performed with the same Chrome had however demonstrated something extremely precise:
H2 veloce
H3 lento
H2 nuovamente veloce
HTTP/3 throughput was also surprisingly compatible with the limit produced by:
64 KB / RTT
The NGINX documentation confirmed that:
http3_stream_buffer_size 64k;
This is the default value.
The source code also confirmed that this value is stored in the QUIC configuration and that the default implemented during merging is indeed 65536 bytes.
But the truly decisive step came when analyzing the connection lifecycle.
In ngx_http_init_connection() NGINX starts from default_server associated with the address:port pair and, when it recognizes a QUIC listener, immediately calls ngx_http_v3_init_stream().
Inside this last function the HTTP/3 configuration is retrieved from the available context and the QUIC structure is passed to ngx_quic_run().
That's why you should set a huge:
http3_stream_buffer_size 16m;
only in the second virtual host it had not changed the result.
Moving the configuration into the global context instead:
http {
http3_stream_buffer_size 1m;
}
The limitation disappeared and HTTP/3 finally started transferring files at a speed comparable to HTTP/2.
The case is interesting not because it simply teaches how to increase a buffer.
The real lesson is another.
A syntactically correct configuration is not necessarily applied at the stage of the protocol in which we imagine it to be applied.
When working with technologies like QUIC, TLS, HTTP/2, and HTTP/3, knowing only the configuration directives may not be enough.
Sometimes you have to follow the connection all the way into the source.
And it's right there, between a:
default_server->ctx
and a call to:
ngx_quic_run()
that we found the difference between a download lasting a minute and a half and one lasting a few seconds.

