

Table of contents of the article:
For over a decade, the hosting market has operated according to a rather simple and, for a long time, extremely effective formula: sell hosting plans by providing a certain number of gigabytes of space, a PHP interpreter, a MySQL or MariaDB database, and an Apache web server.
Over the years, the offering has evolved. Apache has been joined or replaced by technologies considered more high-performance, such as LiteSpeed or NGINX, while more advanced services have included Varnish, Redis, object cache, NVMe storage, HTTP/2, HTTP/3, and increasingly sophisticated PHP-FPM configurations.
Essentially, the concept of optimized WordPress hosting has been built almost exclusively around the server-side technology stack for years.
And for a long time it worked.
It worked because the context was profoundly different from the current one and because there was a much clearer separation of roles: the hosting did the hosting, the systems administrator did the systems administrator and the developer did the developer.
For over ten years the separation of roles has worked
The hosting provider took care of the infrastructure: servers, network, operating system, PHP, databases, backups, disk space, service availability and, in the best cases, security and monitoring.
The developer, on the other hand, took care of the actual site: he chose the theme, installed and configured the plugins, developed any customizations and managed the general setup of the project.
The end customer, very often, did not even know the name of the Hosting Provider where their site was hosted.
In many cases, hosting was purchased directly from the developer or agency, who then invoiced the end customer using their own markups. For the client, the only thing that existed was the professional who had created the site and who continued to be their point of contact.
Even the Web, from an automatic traffic perspective, was very different.
There were certainly search engine crawlers: Google, Bing, Yahoo, Yandex, and a few others. But there weren't the number of bots, scrapers, scanners, automated services, comparison tools, SEO crawlers, and especially AI bots that today continually visit every publicly accessible site.
Words like AI Bot, language model crawler, or large-scale automated scraping didn’t even exist in the minds of most developers and system administrators.
Everything therefore functioned in a more linear manner and in relatively watertight compartments.
If the site was slow, the developer would pass the buck to the systems administrator.
The system administrator checked CPU, memory, disk I/O, PHP processes, database connections, and the server's overall health. If no infrastructure issues were identified, one of the typical checks was to observe what was happening on MySQL or MariaDB.
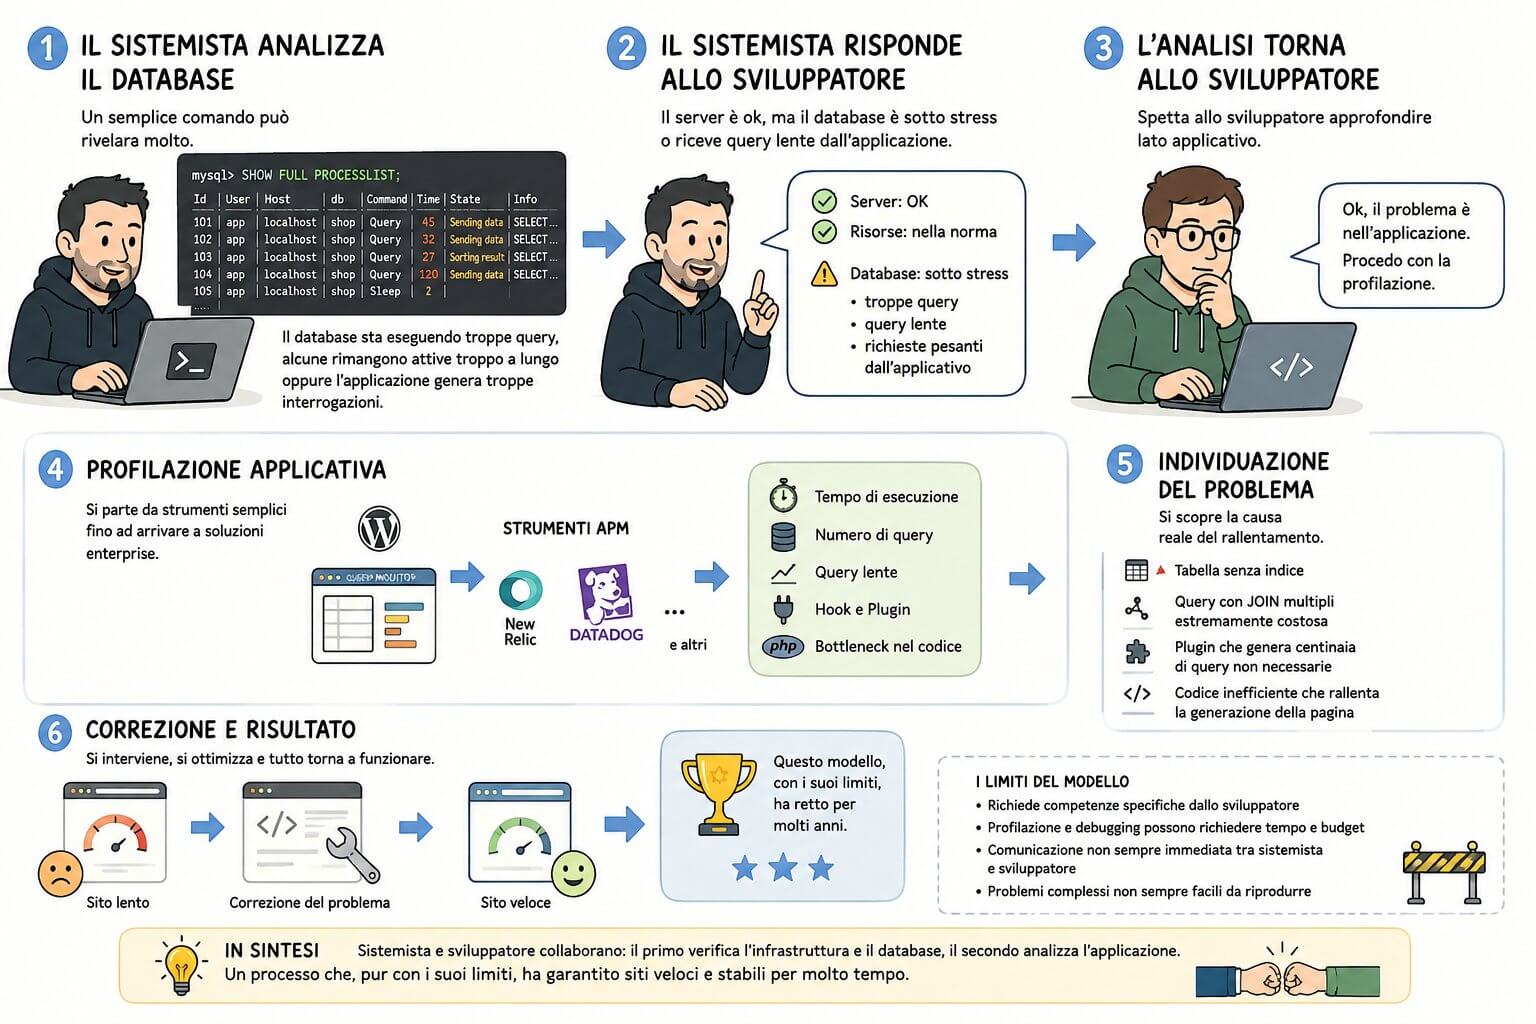
Even a simple:
SHOW FULL PROCESSLIST;
This might be enough to understand that the database was executing too many queries, that some queries were remaining active for too long, or that the application was generating an abnormal number of queries.
At that point the systems engineer could respond to the developer by saying, essentially: the server isn't having any particular problems, but the database is working too hard or there are slow queries coming from the application.
The responsibility for the analysis then fell to the developer who, budget permitting, could eventually decide to get his hands dirty with actual application profiling.
In the WordPress world, you could start with the simple Query Monitor. In more structured projects, you could use more advanced tools like New Relic, Datadog, or other APM platforms.
We identified the table without an index, the extremely expensive query with multiple JOINs, the plugin that performed hundreds of unnecessary queries, or a specific piece of code that slowed down the entire page generation.
The problem was fixed and everything worked again.
This model, with all its limitations, has held up for many years.
In recent years this formula has stopped working
Over the last few years the situation has changed profoundly.
Today, when a site is slow, the customer almost always blames the Hosting.
From his point of view, it's also a pretty natural association: the site is slow, the site is hosted on a server, the server is provided by the hosting provider, so the problem must be the hosting.
The non-technical customer isn't expected to know the difference between a saturated CPU, a query without an index, a PHP loop, an external HTTP request that takes five seconds, a hook that executes hundreds of times, or a poorly configured database.
He sees a page that takes too long to load and looks for a simple explanation.
The last two migrations of this type we managed involved two e-commerce sites: a PrestaShop and a WooCommerce.
Both were considered slow. In both cases, the respective customers were convinced that the hosting provider was to blame. And in both cases, at least initially, the developers had essentially followed the same interpretation, without really questioning that the problem might be in the application or the database.
The first case concerned a PrestaShop e-commerce site with PayPlug installed.
The developer had left a feature related to the Oney payment active, which, in fact, was not used on the site.
The behavior identified during profiling was very precise.
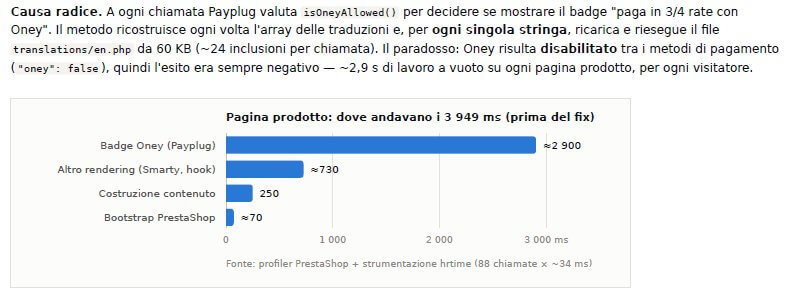
On each call, PayPlug executed isOneyAllowed() to decide whether to show the badge for paying in three or four installments with Oney.
The problem was that this method rebuilt the translation array for each individual string each time, repeatedly reloading and re-running the translations/en.php file , a file of about 60 KB.
We are talking about approximately 24 inclusions per single call.
The paradox was that Oney was disabled among the payment methods.
So all that work was done to come to the conclusion, each time, that the badge should not be displayed.
Profiling made the problem even more evident.
On a product page that took a total of approximately 3.949 milliseconds to process, nearly 2.900 milliseconds were attributable to PayPlug’s Oney badge alone.
The rest of the rendering, including Smarty and the hook, took about 730 milliseconds. Building the content took about 250 milliseconds. PrestaShop bootstrapping took about 70 milliseconds.
In other words, approximately 2,9 seconds of processing time was wasted on each product page, for each visitor, to determine that a disabled payment method should not be displayed.
It wasn't an Apache problem.
It wasn't an NGINX issue.
It wasn't a problem with MariaDB, the speed of NVMe, or the amount of RAM available.
It was an application problem that could only be identified by profiling.
The second case instead concerned a WooCommerce.
The symptom was a load average that was consistently between 7,7 and 7,9 on an 8-core machine , despite traffic being essentially negligible.
There were no peaks followed by periods of normality. The load remained high for a prolonged period, practically plateauing.
The analysis allowed us to identify the cause in an infinite loop present in the Woodmart 8.1.2 theme , precisely in the logic used for navigation between the previous and next product.
The problem was triggered by a very particular situation: two consecutive products were published but simultaneously excluded from visibility in the catalog.
In that condition the code kept looking for a valid previous or next product without successfully reaching an exit condition.
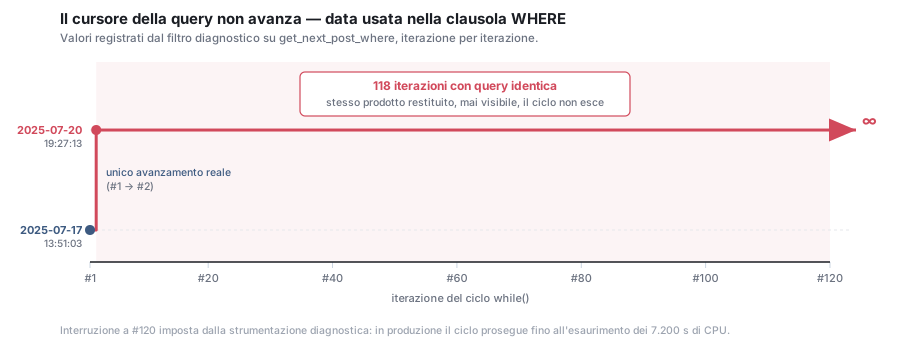
The cost of a single request was up to 7.200 CPU seconds.
Translated into more immediate terms: a single request could keep a core fully busy for about two hours.
And even the cache couldn't protect the system.
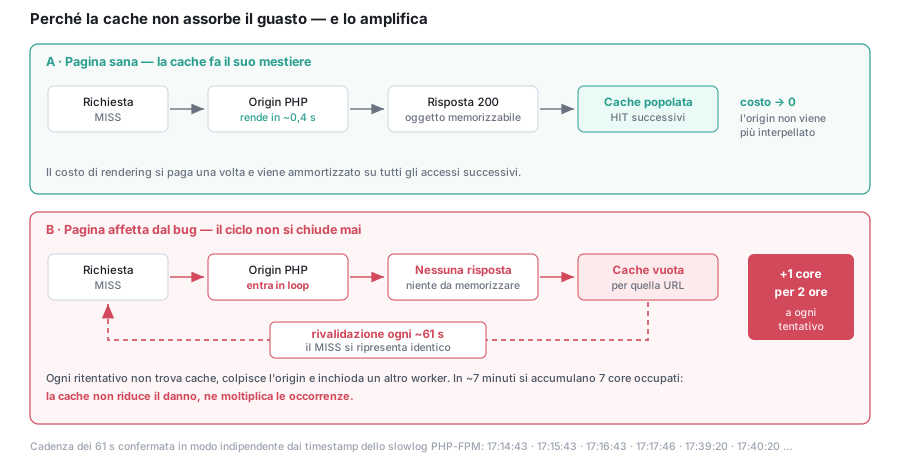
This is important, because caching is often thought of as a kind of universal solution: if your site is slow, you cache everything and the problem goes away.
But a cache can only store a response that is actually produced.
In this case, the MISS entered the loop and never generated a complete, and therefore memorable, response. The next request in the MISS repeated exactly the same behavior.
The solution was an application intervention through a mu-plugin , introducing an SQL exclusion of non-visible products and above all a maximum limit on iterations.
The result after the intervention was extremely clear: the load average went from 7,70 to 0,28 , the TTFB from 1,17 seconds to 0,36 seconds and about 7 cores were returned to normal service.
Again, it wasn't a matter of buying a more powerful CPU, increasing RAM, or changing web server technology.
We had to find the problem.
But then why do we argue that the problem could also be with the Hosting?
In both cases, customers had placed the responsibility for performance on their respective Hosting Providers.
Even their developers had not initially seriously questioned this hypothesis.
When they came to us asking what could be causing the slowness, we also argued that the problem could probably be related to the hosting.
Some might see dishonesty in this statement.
In fact, it would have been inappropriate to state with certainty that the responsibility lay with the previous provider before carrying out an analysis, profiling and measurements.
And there's not much to discuss about this: first you measure and then you conclude.
But let us explain why, deep down, we still believe we are not completely wrong.
As we said at the beginning, up until now the Hosting Provider has generally acted as the Hosting Provider.
Payment of a fee, automatic account creation, provision of username and password for Plesk or cPanel, availability of PHP, database, web space, backups and that's it.
But today the question is different: who cares about understanding why the site is slow?
Who checks, for example, that during an old migration or import the MySQL or MariaDB tables were at least converted from MyISAM to InnoDB when appropriate?
Who checks that there are no tables without adequate indexes?
Who notices an application loop?
Who checks for particularly slow external HTTP requests?
Who analyzes inefficient SQL queries, plugins that perform thousands of unnecessary operations, or anomalous application behavior?
If you ask this question to a traditional hosting provider, especially to a system purist, the answer will probably be immediate:
“The customer.”
Or:
“The customer developer.”
And let's be clear: from the point of view of the traditional division of responsibilities, he is absolutely right.
The developer should take care of this.
But what if the developer doesn't know how to do it?
What if you have no experience with application profiling, SQL analysis, or debugging problems that only manifest under certain conditions?
What happens if the client doesn't have the budget to commission profiling days from a specialist?
And above all, what happens when, without a precise technical explanation, the simplest conclusion inevitably becomes:
“It's the hosting that's slow.”
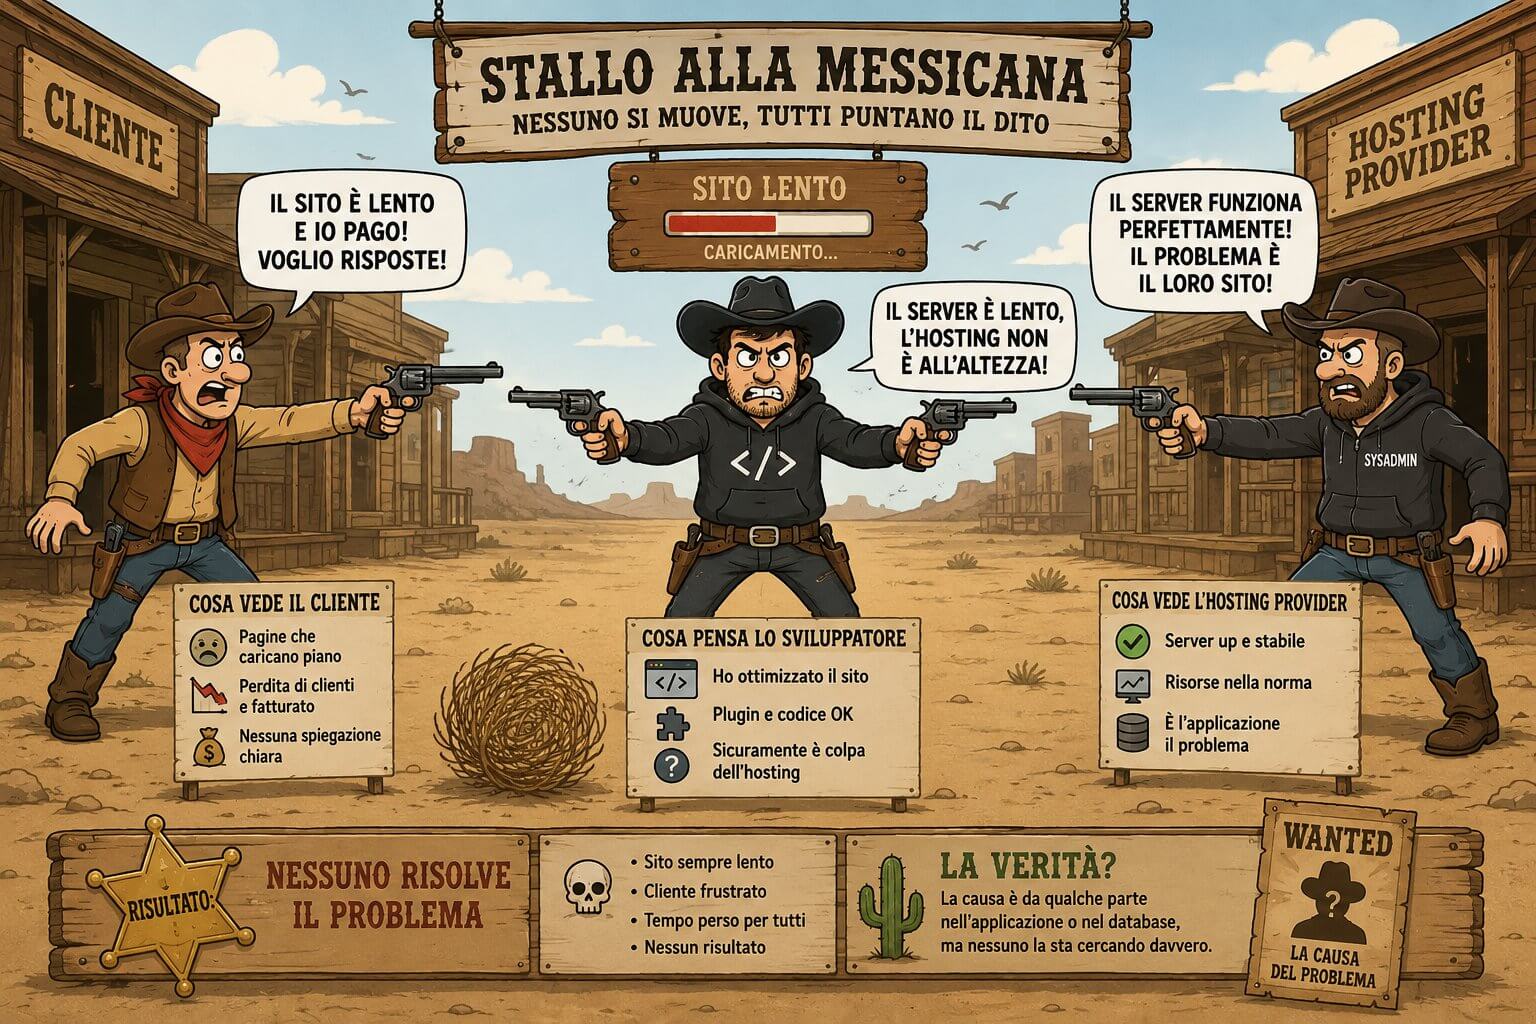
We reach a stalemate where no one can really move.
The paying customer, who is not technical, sees his site as slow and complains to the developer.
The developer complains to the hosting provider.
The Hosting Provider checks the server, CPU, RAM, and storage and responds that from their point of view everything is working correctly and that the problem is with the application.
The developer, in turn, may not have the budget, tools, or skills to tackle a problem of that complexity.
And the customer continues to have a slow site.
Days pass. Then weeks. Sometimes a month goes by.
At that point the same thing almost always happens.
The developer, who in 90% of cases is the person most trusted by the client and who often has carte blanche to choose the hosting provider, decides that the time has come to change hosting.
Perhaps without having first carried out a real application profiling.
Perhaps without having done, in addition to an examination of conscience, also an examination of the code, the database and the behavior of the application.
And so a Hosting Provider can lose a customer even though it has no direct responsibility for the technical problem that caused the slowness.
But here we come to a further paradox.
When a hosting provider tells a developer or customer that the problem is with the application and not the server, they should also be able to justify that response.
It's not enough to say:
“The other clients are working fine, so the problem is definitely your site.”
This is plausible reasoning, but it is not a diagnosis.
We should arrive with numbers, metrics and measurements.
You should be able to tell that a certain function is taking 2,9 seconds, that a query is being executed thousands of times, that a PHP worker is busy for hours, or that a certain HTTP call is blocking page generation.
It is the principle that we have always summarized with a very simple formula:
measure to decide.
The problem is that measuring costs.
It takes time and requires skills.
And often those skills aren't even present internally at the hosting provider, because a hosting company is typically built around systems engineers and not necessarily developers, DBAs, or application profiling specialists.
The result is a continuous buck-passing between the hosting provider and the developer.
The first one claims that the server is working.
The second claims that the site was working before.
And in the middle, the one who always pays the price is the paying customer.
This is why optimized WordPress Hosting is no longer enough today.
For years we have been arguing that hosting services can no longer be run and provided exactly as they were twenty years ago.
Today, providing hosting for specific CMSs like WordPress, WooCommerce, PrestaShop, Magento, Joomla, or Drupal cannot simply mean providing fast web space.
It also means being able to deal with difficult situations when they arise.
It means being able to distinguish an infrastructure problem from an application problem.
It means having the ability, when necessary, to dive down a level and understand what's really happening inside the application.
Some of our competitors might object that all this comes at a cost.
And he would be right.
If a profile requires four hours of work by an expert technician, it is not economically sustainable to include it without limits within a hosting that costs 50 or 100 euros a year.
You would inevitably end up at a loss.
But it is precisely for this reason that we believe it is pointless to continue selling something at a low price that, when it is really needed, is unable to solve the customer's problem.
Our services start at 27 euros per month , which can be around three times higher than those of a budget hosting provider.
But the type of service changes completely, the approach changes and above all the mindset towards the customer and their business changes.
We're not interested in selling a hosting plan simply to add a new customer and a new invoice.
We're committed to providing hosting that works and, when faced with complex situations, can truly differentiate itself from other providers.
The testimonials that are valuable to us are those of the type:
“I changed three providers and none of them were able to solve the problem until I migrated to Managedserver.it.”
To achieve this result, simply installing NGINX is not enough.
It's not enough to just put Redis.
It's not enough to use NVMe storage or configure PHP-FPM perfectly.
These technologies are essential and continue to make a difference, but they only represent part of the problem.
Times have changed and approaches must change too.
It no longer makes much sense, at least for those who want to offer a high-level Managed service, to be haughty purists of systems alone, refusing on principle to lower a level and get their hands dirty with the code or the application.
If a Linux machine is running perfectly but a single WordPress hook is consuming four seconds per request, the client problem still exists.
If MariaDB is configured perfectly but a query without an index scans millions of rows with each page load, the site is still slow.
If Varnish is configured correctly but a MISS request enters an infinite loop and never produces a measurable response, the cache will fail to save the system.
If PayPlug spends almost three seconds determining that a disabled payment method should not be shown, adding more cores simply means wasting computational resources faster on something that shouldn't be run that way.
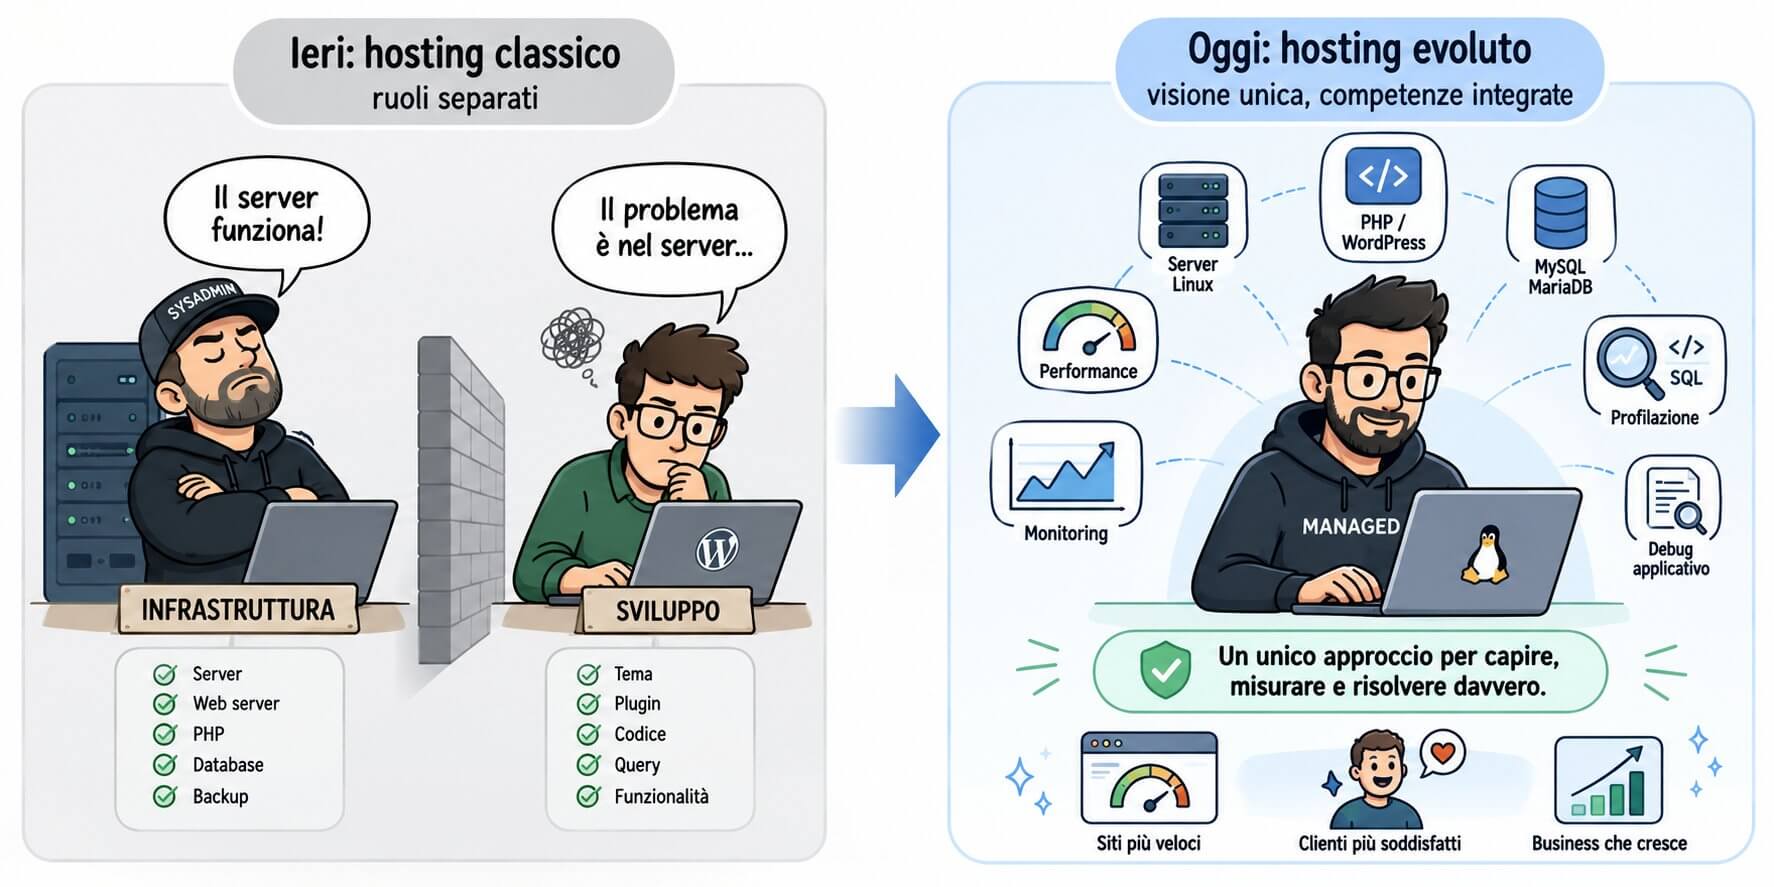
Providing high-quality, high-level hosting today means having a comprehensive vision.
It means knowing Linux systems, but also knowing how to read the application's behavior.
It means understanding PHP, SQL, MySQL, and MariaDB.
It means knowing how to perform profiling, interpret metrics, identify a bottleneck and possibly get to the cause.
It means being able to not only say “the problem is not the server” , but to add:
“The problem is here, these are the numbers that prove it and this is the way to solve it.”
This doesn't mean a hosting provider should become the client's development agency for free, nor should they rewrite entire plugins or themes for a simple monthly fee.
However, it means having the necessary skills to go beyond the surface.
Because the end customer, in the end, isn't really interested in the philosophical debate about where the systems engineer's work ends and the developer's begins.
The customer sees something much simpler.
He has a website.
He's paying for it.
That site needs to work.
And when it doesn't work, someone has to be able to figure out why.
This, in our opinion, is the true evolution of Managed Hosting.
Don't replace systems engineering with development, nor expect every technician to know how to do everything. Instead, build a service capable of observing the entire stack: infrastructure, operating system, web server, PHP, database, cache, SQL queries, code, and application behavior.
The old concept of optimized WordPress hosting, simply meaning a fast server with NGINX, LiteSpeed, Redis, or Varnish, isn't wrong.
It simply became insufficient.
Because today value doesn't just consist in making resources available.
It's about knowing what's happening when those resources are misused.
It consists of measuring.
In understanding.
And, when possible, in solving.
Everything else belongs to a way of hosting that the market, the complexity of modern CMS, and customer needs have now surpassed.

