

Table of contents of the article:
There are migrations where the result is exactly what you expect. The client arrives from a hosting provider that can no longer guarantee adequate response times, moves to a more high-performance, elite infrastructure like ours, implements a server stack optimized for WordPress and WooCommerce, and the problem disappears.
Well, this one I'm about to tell you is NOT one of those stories.
In this case, the client arrived from another hosting provider complaining of significant web performance issues, unsatisfactory loading times, and site behavior that was difficult to explain in relation to actual traffic . The project was a WooCommerce e-commerce site, and when migrating to Managed Server Srl, the initial belief was quite simple: by moving the site to a properly sized infrastructure and our optimized server-side stack, all (or most) of the issues would disappear.
The customer thought so (after all, we are famous for this).
We thought so too.
Well, we were both wrong!
The new infrastructure was definitely more than adequate. NGINX, PHP-FPM, MariaDB, application caches like REDIS Object Cache, and HTTP caches like the prestigious Varnish Cache were configured to handle loads far exceeding the site's actual performance. Yet something still didn't add up. Most importantly, a massive CPU load continued to appear under conditions where, looking at the traffic, that load simply shouldn't have existed.
What initially seemed like a normal system migration and optimization job has now turned into something that, in theory, should be on the other side of the fence: real application debugging within WordPress, WooCommerce and the Woodmart theme.
And this is precisely where a managed service demonstrates a substantial difference compared to simply providing hosting. When the graphs show that the server is working, the database isn't saturated, the storage isn't waiting, the network isn't congested, and the cache doesn't explain the phenomenon, you can't keep changing PHP settings hoping the problem will go away.
At some point you have to get your hands dirty.
The migration had solved the server, not the problem
The environment on which the issue was analyzed had 8 vCPUs and 64 GB of RAM , with AlmaLinux 9.8, NGINX, PHP-FPM 8.3.32, MariaDB, WordPress 7.0.3, WooCommerce 10.9.3, and Woodmart 8.1.2. The catalog had 479 published products, and the installation used 28 active plugins.
In other words, we weren't looking at a massive WooCommerce site running on an underpowered VPS. Nor were we looking at a server that was constantly swapping or waiting for storage.
The most important fact was something else.
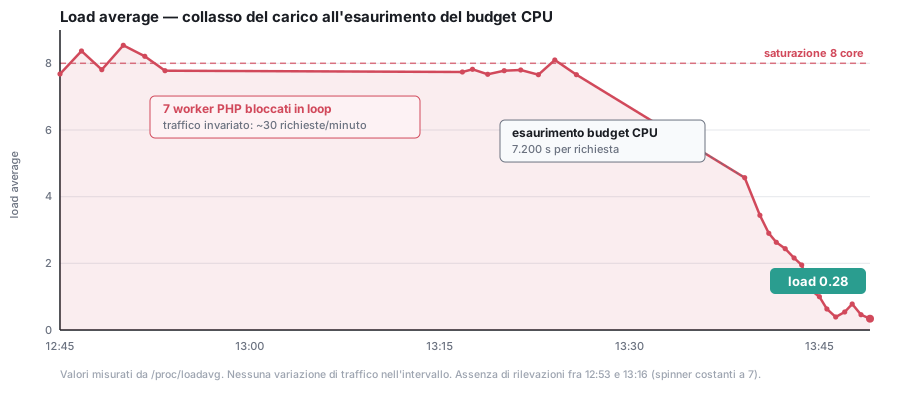
With traffic in the order of around 30 requests per minute , including static assets, the server had a load average consistently in the order of:
7.70 / 7.83 / 7.90
on an 8 core machine that is 100% CPU.
Even more interesting was the distribution of CPU time:
- 88,5% users;
- 1,4% system;
- 0,0% iowait.
That fact is worth more than many suppositions.
If a machine is waiting for disk, we expect iowait. If the database is the bottleneck, we typically see queries, locks, waits, I/O, connections, or other similar evidence. If the problem is network-related, we see a different set of signals. Here, however, almost all the time was consumed in CPU userland.
The processor was executing code.
Lots of code.
And he was expecting practically nothing.
This distinction is crucial because it avoids one of the most common mistakes in WordPress performance troubleshooting: mistaking any slowness for a hosting issue.
Hosting can be slow. A database can be poorly configured. PHP-FPM can be underpowered. Storage can be inadequate. Caching can be missing. These are all real problems.
But when seven cores are doing PHP computation almost continuously for a site that receives very few requests, adding hardware just allows the bug to consume more hardware.
The first error of perspective: thinking that the cache was enough
In Managed Server we normally use multiple levels of caching precisely because on WordPress and WooCommerce it is essential to avoid having to rebuild the entire page via PHP and the database for each access.
The case analyzed involved several layers: NGINX proxy cache in microcache configuration, Varnish, and Redis object cache. During debugging, these layers were progressively deactivated to remove variables from the analysis.
However, we also discovered another interesting detail: an edge cache was left active. The header bestcache.io: STALE and a homepage returned in just 15-40 milliseconds demonstrated that some of the early, seemingly “cache-free” measurements were not actually querying the origin directly.
The measurements were then repeated using structurally non-cacheable URLs and cache-busters.
But the real conceptual problem was another and it was unthinkable!
A cache can prevent a job from being executed. It cannot terminate an infinite job.
The model can be simplified as follows:
carico origin ≈ richieste × miss rate × costo del MISS
Almost all cache optimization works on the second factor: the miss rate.
If a page costs 400 milliseconds to generate and we serve it from cache 99% of the time, we've achieved excellent results. The origin rarely pays those 400 milliseconds, and all other requests are served at almost no cost.
But what happens if the MISS cost is not 400 milliseconds?
What happens if the MISS enters a cycle that does not end?
The model changes completely.
The MISS that never becomes a HIT
An HTTP cache can only store a response after that response has been produced.
It may seem obvious, but it is precisely this detail that made this incident particularly insidious.
The sequence was as follows:
- a request arrives for a specific product page;
- the cache does not have the object and records a MISS;
- the request is forwarded to PHP;
- during rendering PHP enters Woodmart's previous/next product navigation code;
- the code enters a loop;
- the request does not end;
- a complete HTTP response is not produced;
- the cache, having received no response, he has nothing to memorize;
- the next request to the same resource is again a MISS.
Therefore, the fundamental passage does not exist:
MISS → rendering → response → cached object → subsequent HITs.
The process gets stuck halfway:
MISS → PHP → loop.
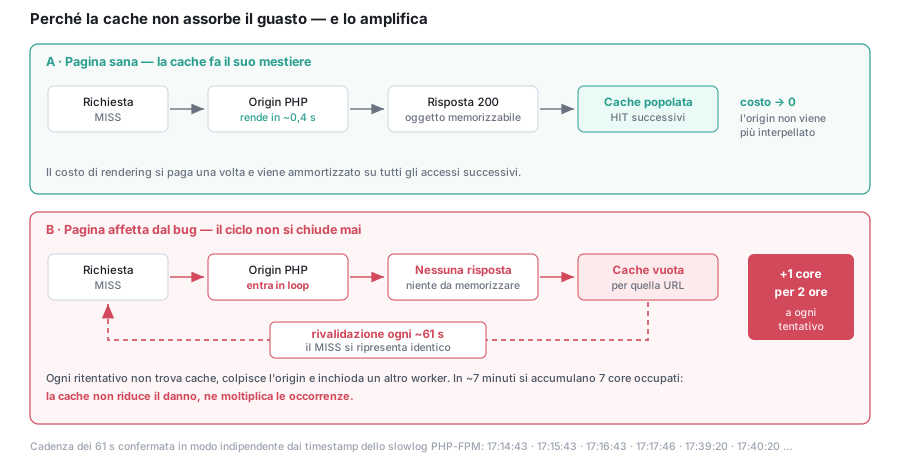
A healthy page produces a cacheable response. The affected page doesn't finish rendering: no objects are created, and each new attempt hits PHP again.
This is one of the most important lessons of the whole case.
Caching does not correct pathological complexity of application code.
It can hide it. It can reduce the frequency with which we encounter it. But if for some reason a request actually needs to reach the origin, the true cost of the application immediately resurfaces.
When the cache stops protecting and starts amplifying
The even more interesting part of the incident is that one of the mechanisms normally used to make a site more robust ended up contributing to the automatic generation of load.
The logs contained requests from 127.0.0.1 towards the problematic URL at extremely regular intervals: about 61 seconds.
The timestamps detected during the analysis showed sequences like:
17:14:43 · 17:15:43 · 17:16:43 · 17:17:46 · 17:39:20 · 17:40:20 · 17:41:23 · 17:42:23
Such a periodicity is compatible with an automatic revalidation mechanism.
And here is the paradox.
The system attempts to revalidate a resource. It doesn't find it ready in the cache and reaches PHP. PHP enters a loop. The revalidation doesn't receive a new valid response. Shortly thereafter, another revalidation starts. This also reaches PHP and uses another worker.
Each attempt adds a process that consumes essentially an entire core.
The cache, designed to offload the origin, therefore behaved as a periodic generator of the problem in this particular failure mode.
Not because the cache was misconfigured in the traditional sense, but because the application was no longer able to satisfy the fundamental contract on which a cache is based: receive a request and, sooner or later, return a response.
Seven PHP workers, seven cores almost fully occupied
Inspection of PHP-FPM processes immediately separated two worker populations.
On one side were normal processes, with tens of seconds of CPU usage accumulated over many hours.
On the other hand, there were processes that, despite having been born in the same time interval, had accumulated thousands of seconds of CPU time.
Direct sampling of /proc/PID/stat, carried out at ten-second intervals, quantified the behavior: the seven anomalous processes consumed approximately 98% of each core continuously.
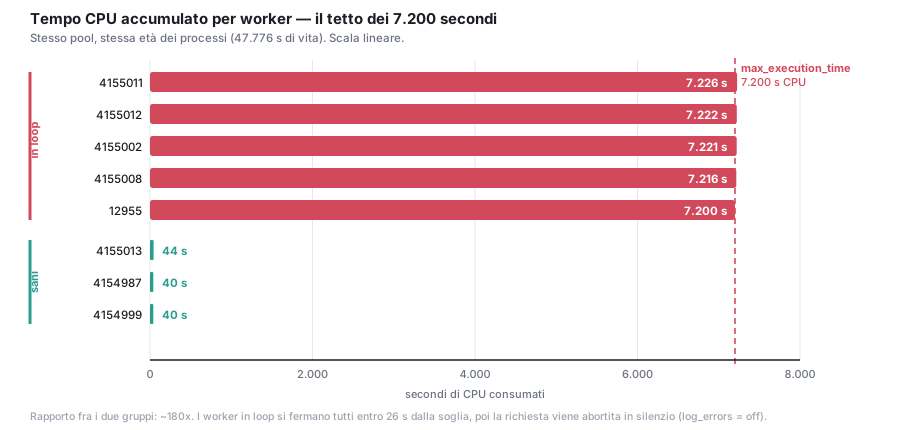
On an eight-vCPU machine, this essentially means leaving just one core for the rest of the system.
And here it is also useful to look at the PHP-FPM configuration:
pm = static
pm.max_children = 32
request_terminate_timeout = 7200
php_admin_value[max_execution_time] = 7200
php_admin_flag[log_errors] = off

; nessun pm.status_path
; nessuno slowlog
The configuration allowed for up to 32 concurrent PHP workers, but of course, 32 workers doesn't equal 32 cores . If seven workers fit into a CPU spin on an eight-core machine, the available computational capacity is already almost completely occupied.
Furthermore, both request_terminate_timeout is max_execution_time were set to 7200 seconds.
Two hours.
This means that a single pathological request could theoretically consume 7200 seconds of CPU time, or one core for two hours , before being terminated.
We're not talking about a page that takes four or five seconds to load.
We are talking about a request that can turn into two core hours of useless work.
Why Redis couldn't solve anything
When it comes to slow WooCommerce, Redis is often touted as a universal solution.
Redis is very useful, but you need to understand what problem it solves.
An object cache reduces the cost of retrieving objects, options, results, and data that would otherwise require repeated database access. If an application runs many identical queries, or continually rebuilds the same objects, Redis can have a significant impact.
In our case, however, we had:
0,0% iowait.
Furthermore, the RSS memory of the involved processes remained identical to the byte even after tens of minutes . One of the samples reported, for example:
635436 kB → 635436 kB
No growth.
No significant new allocations.
No compatible I/O activity was detected with a workload that was continuing to query a database.
The process was running on data already resident in memory.
It was a cycle of control that did not progress.
In such a situation, Redis is orthogonal to the problem. It can speed up the retrieval of data used before entering the loop, but once you enter an infinite loop, there's no object cache capable of advancing the variable that should trigger the exit condition.
It wasn't MariaDB, it wasn't OPcache, it wasn't wp-cron
Serious debugging isn't about quickly finding a plausible culprit.
It consists above all in methodically eliminating all plausible culprits who are not responsible.
Several hypotheses were tested during the analysis.
Action Scheduler had only 22 pending actions and no in-progress actions. Jetpack Full Sync was not blocked. OPcache had a hit rate of 99,73% , with no OOM restarts and no hash restarts. The autoload options occupied approximately 0,56 MB across 1.493 rows, a value inconsistent with an explanation for the observed load. There were no recurring schedules with zero intervals.
Even the hypothesis of a botnet that hit parameters ?per_row= it was excluded because those requests were answered 444 directly at the NGINX level, without reaching PHP.
The database was not showing the saturation expected from a SQL problem and, as mentioned, the system was recording 0% iowait.
Profiling a healthy page also showed that the entire plugin bootstrap wasn't a major anomaly. A test request finished loading after the mu-plugins in approximately 0,934 seconds, with 332 queries and 48 MB of peak memory.
Some values detected:
core:wp-includes                                     0,136 s
plugins:yith-woocommerce-advanced-reviews-premium   0,094 s
plugins:woocommerce                                  0,070 s
plugins:woocommerce-paypal-payments                  0,019 s
plugins:wordpress-seo                                0,012 s
No plugin showed a cost that could explain seven continuously busy cores.
These tests are also important from a methodological point of view.
We could have disabled plugins at random, seen the load temporarily drop or behavior change, attributed the cause to an accidental correlation, and called it a day.
This is not our way of working.
A cause is a cause when there is a chain of reproducible evidence linking the symptom to the responsible code.
The comparison that definitively excluded the infrastructure
Another particularly significant finding came from a second PHP pool hosted on the same server.
Same operating system.
Same NGINX.
Same PHP.
Same MariaDB.
Same underlying physical or virtual machine.
Workers in that pool were showing a total CPU usage of around 57-62 seconds versus over 5.000 seconds accumulated by the WooCommerce outlier workers we analyzed.
If the problem had been the kernel, virtualization, physical CPU, storage, MariaDB, or general host configuration, it would have been difficult to explain such a clear separation between two workloads sharing the same infrastructure.
The problem followed the site.
And when a problem is in the code and not the server, you need to stop tuning the server and start looking at the code.
The next problem: we didn't have the tools normally used to do this job.
Identifying that the problem was an application one was only half the battle.
Now we needed to figure out where PHP was spending all that CPU.
And this is where the incident became particularly interesting.
Standard tools that we would normally use to inspect a running process were either unavailable or unusable in the specific context.
ptrace, strace e gdb could not be used on FPM children as needed. The extension pcntl It was not present. No profilers like XHProf or Tideways were installed.
PHP-FPM had not configured pm.status_path.
A slowlog was not configured.
And especially:
log_errors it was deactivated.
The result was almost perfect in making this class of problems invisible.
A request would enter the loop, continue to consume CPU, the client would eventually drop the connection, and the PHP process would continue to run until the two-hour timeout.
No application errors.
No stack trace.
No useful PHP logs.
No 504 necessarily correlates to the actual duration of the process.
From an observability point of view it was almost a black hole.
We then built the debugging tools that were missing
When you can't directly observe the stack of a PHP-FPM process in production, you need to find other ways to correlate:
PID → HTTP request → CPU behavior → application path.
Three diagnostic tools have therefore been temporarily introduced.
1. A START/END request tracer
The first was extremely simple conceptually.
At the beginning of the request, the timestamp, PID, identifier, and URI were recorded. At the end of the request, a shutdown handler recorded the corresponding END line.
@file_put_contents(
$log,
sprintf(
"%s\tSTART\t%d\t%s\t%s\t%s\n",
gmdate('H:i:s'),
getmypid(),
$id,
$method,
$uri
),
FILE_APPEND
);

register_shutdown_function(function () use ($id) {
@file_put_contents(
$log,
sprintf(
"%s\tEND\t%d\t%s\t%.2fs\n",
gmdate('H:i:s'),
getmypid(),
$id,
microtime(true) - $t0
),
FILE_APPEND
);
});
A healthy request then produces a pair:
START → END
A blocked request instead produces:
START → ...
without END.
To extract the requests still in flight, it was sufficient to correlate the two types of records:
awk -F'\t' '$2=="START"{s[$4]=$0} $2=="END"{delete s[$4]} END{for(k in s) print s[k]}' req-trace.log
This tracer isolated four orphaned requests, all focused on the same URL.
And above all, those requests showed the same periodicity observed in the behavior of the processes.
2. A spin watcher for PHP-FPM processes
The second instrument sampled periodically /proc/PID/stat.
The goal was not to profile PHP at the function level, but to detect a much simpler condition:
this process keeps hogging CPU at almost 100% without terminating?
When the watcher detected a spinning worker, it could correlate its PID with the request tracer and determine which HTTP request was actually executing in that process.
This step eliminated a huge portion of the search space.
3. Breadcrumbs and backtraces directly from the application
The third instrument is the one that definitively closed the case.
Since we couldn't conveniently query the process from outside, we had the application itself take a snapshot of its own stack while the loop was running.
A global hook counted executions and, when certain thresholds were reached, acquired a debug_backtrace().
add_action('all', function () {
$n = ++$GLOBALS['__bc_n'];

```
if ($n === 20000 || $n === 80000 || $n === 200000) {
    $bt = debug_backtrace(
        DEBUG_BACKTRACE_IGNORE_ARGS,
        80
    );

    // Serializzazione diagnostica su file.
}

if ($n > 200000) {
    exit('diagnostic abort');
}
```

});
The result was impressive.
In a single request the breadcrumb reached 300.000 hooks in about 4,2 seconds.
The hook alloptions was invoked 26.684 times higher.
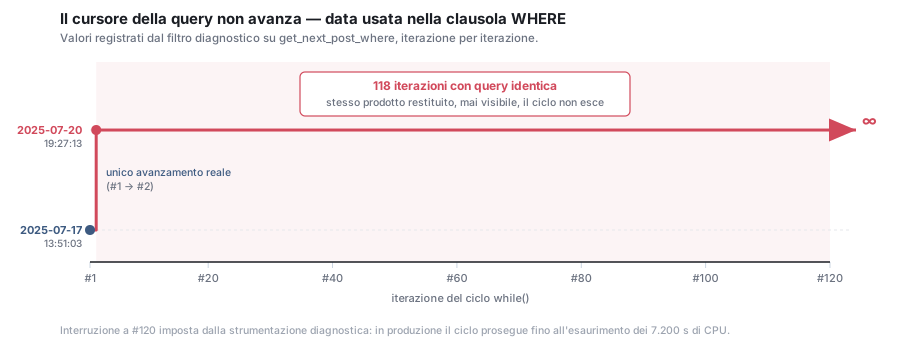
At that point we were no longer hypothesizing a loop.
We were watching him.
The stack trace leads directly into Woodmart
The backtrace captured during the loop showed this sequence:
#5  wc_get_product()
themes/woodmart/.../class-adjacent-products.php:92

#6  WC_Adjacent_Products->get_product()
themes/woodmart/.../functions.php:588

#7  woodmart_get_next_product()
themes/woodmart/woocommerce/single-product/navigation.php:13

#8  wc_get_template()
themes/woodmart/woocommerce/content-single-product.php:203

#9  load_template()
wp-includes/template.php:816
The path was now extremely clear.
We weren't observing a checkout.
We weren't seeing a particularly heavy product query.
We weren't looking at a REST call, a cron job, or a sync.
The loop occurred while building the Woodmart theme's previous/next product navigation .
As an independent check, PHP-FPM's slowlog has also been enabled in the meantime.
Su 24 stack traces acquired, 24 contained woodmart_get_next_product.
Two different tools, based on different mechanisms, arrived at the exact same point.
This is the difference between a guess and a diagnosis.
The code that could no longer break out of the loop
The critical point was in the file:
wp-content/themes/woodmart/inc/integrations/woocommerce/modules/class-adjacent-products.php
The relevant structure of the method was this:
public function get_product() {
global $post;

```
$product               = false;
$this->current_product = $post->ID;

while ( $adjacent = $this->get_adjacent() ) {
    $product = wc_get_product( $adjacent->ID );

    if ( $product && $product->is_visible() ) {
        break;
    }

    $product               = false;
    $this->current_product = $adjacent->ID;
}

if ( $product ) {
    return $product;
}

return false;
```

}
The intention of the code is understandable.
Starting from the current product, the adjacent product is searched. If the found product is visible, it is returned and the loop ends. If it is not visible, it is discarded, the current reference is updated, and the search continues.
Conceptually:
prodotto corrente → adiacente → è visibile? → sì: break / no: continua
The problem, however, arose with a particular data configuration: two consecutive products were published but excluded from the catalogue.
In that condition, the adjacent product search mechanism could enter a situation where the loop no longer reached a valid exit condition.
Navigation was therefore unable to converge towards a visible product or towards the end of the sequence.
The method continued to recall the search logic and reconstruct the objects involved.
There was no maximum limit to the iterations.
And a while loop without a safe limit is only correct if we can show that at each iteration the state necessarily advances towards a terminal condition.
In the observed case this property was not guaranteed.
The bug didn't make the page slow: it made the request non-terminating.
It is important to use the correct terminology.
To say that “Woodmart was slowing down WooCommerce” would be a technically weak description.
We weren't measuring a function that took two seconds instead of a hundred milliseconds.
We weren't even measuring a SQL query to optimize.
We were facing a termination problem.
The request could continue up to the limit imposed externally by PHP-FPM.
In our environment that limit was 7.200 seconds.
For this reason, the unit cost of a single pathological request could reach:
7.200 seconds of CPU.
A core.
For two hours.
And just a few requests of this type, even automatically generated about a minute apart, were enough to transform a practically empty machine into one close to saturation.
Because the traffic appeared innocent
This dynamic also explains another feature of the problem that might initially have seemed counterintuitive.
The client saw a loaded server despite having very little traffic.
We usually tend to correlate load with the number of requests:
more visits → more PHP → more queries → more CPU.
Here the correlation was completely different.
A healthy request could cost a few hundred milliseconds.
A pathological request could cost 7.200.000.
At that point, simply counting requests per minute becomes almost meaningless.
Ten thousand cache HITs can weigh less than a single request entering CPU spin.
And this is one of the reasons why evaluating a hosting service solely on the basis of “how many visits it can handle” is often a metric devoid of technical meaning.
You need to know how much a request costs.
The fix: Prevent non-visible products from entering the path and introduce a limit
The solution adopted was not to further increase the server's power.
It wouldn't have made sense.
We have introduced a mu-plugin that intervenes on the logic responsible for the selection, with two security principles.
The first is to prevent the invisible products that generate the pathological condition from being continuously proposed as candidates by the SQL search.
The second consists in introducing a maximum limit to the iterations anyway.
This second point is particularly important from a defensive point of view.
Even if we believe we have corrected the specific condition that generates the loop, a code that traverses a sequence of external elements should have a reasonable limit when termination is not mathematically guaranteed.
The concept, in simplified form, is:
$iterations = 0;
$max_iterations = 100;

while ( $adjacent = get_adjacent_product() ) {

```
if ( ++$iterations > $max_iterations ) {
    return false;
}

$product = wc_get_product( $adjacent->ID );

if ( $product && $product->is_visible() ) {
    return $product;
}

// Avanzamento al candidato successivo.
```

}
This example illustrates the fail-safe principle : no “previous/next product” navigation should be allowed to consume a PHP worker indefinitely.
The fix actually applied in this case also moved part of the protection upstream, causing the SQL selection to exclude products that could not be used for that navigation.
This way you correct both levels of the problem:
This avoids feeding the loop with invalid candidates and prevents a future anomaly from turning into an open-ended loop.
The result: from 7,70 load to 0,28
After applying the fix the system behavior changed immediately.
The load average went from approximately:
7,70 the 0,28.
We didn't add any CPUs.
We didn't increase the RAM.
We didn't change the processor.
We have not replaced MariaDB.
We returned about seven cores to the machine that were doing unnecessary work.
The TTFB measured on the affected route also improved significantly, going from approximately 1,17 seconds to 0,36 seconds.
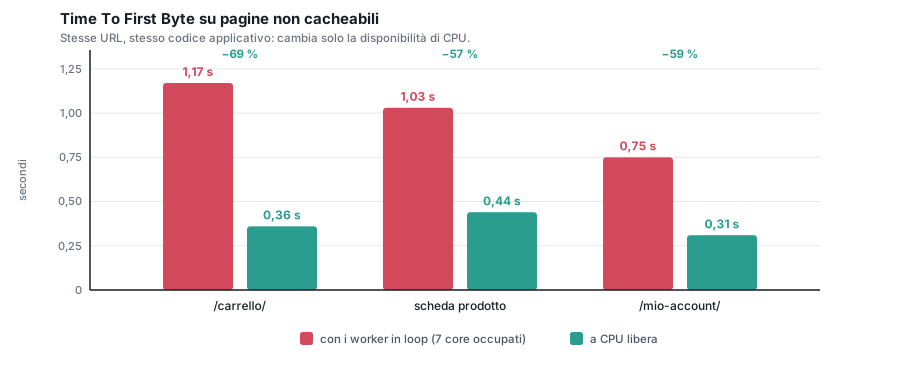
However, this data must be interpreted correctly.
The real result is not an improvement of a few hundred milliseconds on a single page.
The real result is that the entire system stopped losing computational capacity over time.
Before the fix, each new affected request could take up a worker and essentially a core from the service for a very long time.
After the fix, that request reverted to being a normal WooCommerce request: it started, did its job, and finished.
The most dangerous thing about application bugs is that they often look like hosting problems.
This case represents very well a problem that we periodically see in our work.
A site is slow and the first suspect becomes the server.
The RAM is increased.
CPUs are increased.
Redis is installed.
Varnish is added.
It increases pm.max_children.
Timeouts are raised.
We're moving to an even larger server.
And sometimes the site even seems to perform better, because we've simply increased the amount of resources the defect can consume before the user notices saturation.
But this is not optimization.
It is concealment through ability.
If a loop consumes a core, a 4-core machine will crash sooner than a 32-core machine. This doesn't mean the code on the 32-core machine is correct.
It just means it can run multiple loops at once before running out of CPU.
We too had started from the wrong hypothesis
It's worth emphasizing this because in a technical case study, only telling the part where you're right is of little use.
When the customer came from Managed Server, we also thought it was reasonable to expect that the infrastructure change would solve most of the performance issues.
It wasn't an absurd hypothesis.
Many WooCommerce sites we receive actually come from environments with poorly configured PHP, inadequate storage, unoptimized databases, no object cache, generic web servers, too low limits, or aggressively shared resources.
In those cases, migration immediately produces a noticeable improvement.
In this case, no.
The new stack instead did something equally useful: it removed a number of infrastructure variables and made it much more obvious that the residual behavior was not normal.
When you know the server can handle that traffic without difficulty, but you still see seven cores at 98%, the question changes.
Don't ask anymore:
How do we make PHP faster?
Ask:
What exactly is PHP doing with those seven cores?
And it was this question that led us to the solution.
Should managed hosting stop at PHP?
Here we also enter into a question of operational responsibility.
Formally, a hosting provider could stop much earlier; in fact, according to our highly respected colleagues, a hosting provider shouldn't go any further.
You could show the client graphs, demonstrate that the hardware is working, highlight that the consumption is coming from the site's PHP processes, and respond:
This is an application issue, please contact the developer.
In many contracts this would even be a legitimate response.
But a service that truly calls itself managed , especially when it works specifically with WordPress and WooCommerce, must at least be able to understand where the infrastructure ends and the application begins.
And in certain cases that boundary must be crossed, especially if one has the experience and skills to do so, knowing that very few developers today have the ability to do so.
This doesn't mean a hosting company has to become the client's development agency.
This means that when an application anomaly puts the infrastructure at risk, system engineering and application debugging become two parts of the same problem.
A PHP process is simultaneously:
- an operating system process;
- a PHP-FPM worker;
- an HTTP request;
- a WordPress execution;
- a set of hooks;
- plugin and theme code;
- WooCommerce query;
- application status.
Artificially stopping at just one of these levels often means failing to explain what is really happening.
Woodmart was the culprit!
It is also important to avoid incorrect generalizations.
The diagnosis concerns the Woodmart 8.1.2 version present in the analyzed installation and a specific combination of code, catalog status and products published but excluded from visibility.
It would be nonsensical to conclude that “Woodmart is slow,” meaning “Always slow,” or that any site using this theme is subject to the same behavior.
The technical value of the case is another.
A popular component may contain a marginal path that works perfectly for millions of requests and fails only when it encounters a particular combination of data.
This is exactly why these problems are difficult to reproduce.
It's not enough to just install WooCommerce.
It's not enough to just install Woodmart.
It's not enough to open a product page.
You need the specific sequence of products and conditions that cause the code not to converge.
In production, however, that combination did exist.
And that's enough.
The systemic lessons we carry with us
This accident has given us some important confirmations.
An excellent cache HIT ratio does not guarantee that the application is healthy
A cache can keep the frontend fast even when there's a pathological application path underneath. The problem arises with the first MISS, the first invalidation, the first revalidation, or the first structurally uncacheable request.
Load average alone is not enough
A load of 8 can mean completely different things.
You need to understand whether the time is spent on user CPU, system CPU, I/O, locks, runnable processes, or waiting.
In our case, 88,5% users and 0,0% iowaits addressed the survey much faster than any synthetic benchmark.
Huge timeouts aren't free
A 7.200-second timeout may be necessary for certain administrative or batch operations, but applied indiscriminately to a web pool turns an application loop into a resource seized for two hours.
A timeout does not fix the bug, but it determines how long the bug can harm the system.
Observability before the emergency
Not having slowlog, FPM status, and error logging makes it harder to diagnose exactly where those tools would be most useful.
In this intervention we managed to compensate by building temporary tools, but this should not be the norm.
A request without END is worth a thousand guesses.
Correlating the start and end of requests to PIDs was enough to turn a seemingly random problem into a small set of reproducible URLs and processes.
Comparison with a healthy workload on the same host is very powerful
When two sites share the same infrastructure and only one has the problem, you have a natural experimental control that allows you to greatly reduce the hypothesis space.
Web Performance does not only mean Core Web Vitals
When we talk about Web Performance today we often end up discussing only Lighthouse, LCP, INP, CLS, JavaScript, WebP or AVIF images and font loading.
These are important metrics.
But there is a previous level.
Before optimizing browser rendering we need to make sure the origin is computationally sound.
A high TTFB may be caused by a slow server.
It may be due to inefficient queries.
It could be due to a broken cache.
May depend on external HTTP calls.
Or, as in this case, it could be that some part of the PHP rendering fails to finish at all.
Optimizing images and JavaScript while seven cores were running in a loop inside the product browser would have been like unloading the seats of a car with the engine stuck in the throttle.
The difference between a fast server and a fast system
This experience also sums up very well the philosophy with which we approach performance at Managed Server.
A fast server does not automatically guarantee a fast website.
The server is just one layer.
We can have modern CPUs, NVMe, tons of RAM, properly configured MariaDB, NGINX, Redis, Varnish, Brotli, HTTP/2 or HTTP/3, and an excellent caching system.
But if in the rendering path exists:
An infinite loop, a query with the wrong complexity, a remote call that doesn’t finish, an application lock, a recursive cron job, or a function that goes through millions of elements pointlessly—sooner or later, that behavior will emerge.
Infrastructure can mitigate the consequences.
It cannot change the semantics of the code.
In the end, we didn't just make the server more powerful: we made the application stop wasting what it had.
We started from a situation in which the client came from another hosting company convinced that a more performing infrastructure would solve the problem.
We thought it was plausible too.
The migration did indeed bring the site onto a more suitable stack, but it also demonstrated something that no commercial benchmark could have shown:
The fundamental problem wasn't how fast the server executed the code. It was the fact that, under a given condition, that code never finished.
We followed the load from system graphs to PIDs.
From PIDs to HTTP requests.
From requests to WordPress hooks.
From hooks to the PHP stack.
From the stack to Woodmart product navigation.
From navigation to the never-ending cycle.
And from the cycle to the particular condition of the catalogue that triggered it.
Only then was it possible to truly intervene.
The end result was a load dropped from 7,70 to around 0,28 , a TTFB dropped from around 1,17 to 0,36 seconds and, most importantly, seven cores returned to useful work.
Not thanks to a new server.
Not thanks to another cache.
Not thanks to some magical parameter inserted in php.ini.
Thanks to a debug.
And this is perhaps the most important point of the whole story.
There are times when a hosting may be limited to hosting one application.
There are others where, if you really want to understand why that application isn't working, you have to cross the line between systems engineering and development, follow the data to the code, and get your hands dirty.
This was one of those moments.

