
Table of contents of the article:
Every now and then, you snoop around on a client's site and find something you didn't install. It happens often: a third-party plugin, a marketing script, a CDN stuck in front of the origin by an agency. Almost always, it's harmless. Every now and then, however, it's worth investigating further.
Over the past few months, we've encountered Tuurbo.ai on two very different clients: an e-commerce site selling hardware and DIY supplies, and a well-known football publishing network.
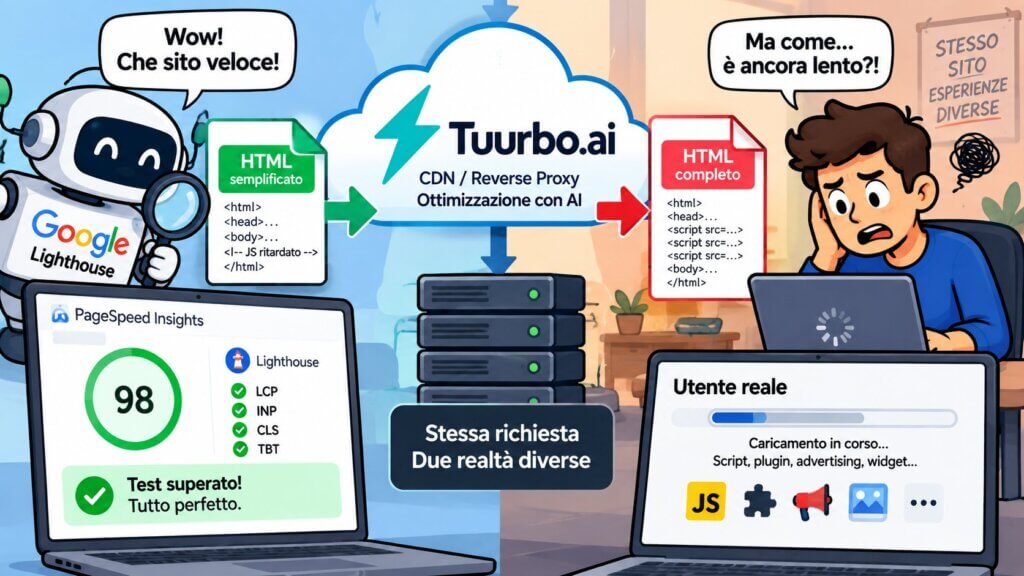
In both cases, the dynamic was essentially the same: suddenly stellar PageSpeed Insights scores, Search Console dashboards that told a different story , and a systems engineer — us — called in to explain why the site “that has a 98 on PageSpeed” still wasn’t passing the Core Web Vitals.
We did what we always do in these cases: we opened the source and started reading the code.
It’s the same path we’ve already followed with Kleecks, iSmartframe, and CDNs that “optimize” Core Web Vitals , and the conclusions, as we’ll see, are quite similar.
What does Tuurbo.ai promise?
Tuurbo.ai is an Italian product of Tuurbo Srl, based in Aci Sant'Antonio, in the province of Catania.
It presents itself as a no-code platform based on “automation and artificial intelligence” that promises to optimize a website in four main areas: speed, on-page SEO, accessibility and security.
The Speed Performance page claim explicitly focuses on performance metrics and the ability to lead the site to excel in evaluations related to Core Web Vitals and PageSpeed Insights.
The company's client list includes major companies: Monrif and Quotidiano.net, Il Resto del Carlino, La Nazione, Il Giorno, Zakeke, Farmamia, Jolicì, Imballaggi2000, Riba Mundo, and others.
There are testimonials from CTOs and e-commerce managers, programs dedicated to agencies and web agencies, and a section of case studies.
In short, we are not talking about an unknown plugin developed over the weekend.
It is a structured commercial product, also used by major companies.
Precisely for this reason, rather than limiting ourselves to the commercial slides and the results shown in the synthetic tests, we preferred to technically understand what was happening between the origin server, Tuurbo and the user's browser.
How Tuurbo.ai Works: CDN, Reverse Proxy, and DOM Manipulation
To understand what we will see later in the loader, we need to clarify a fundamental point: Tuurbo.ai does not work by simply adding normal JavaScript to the site.
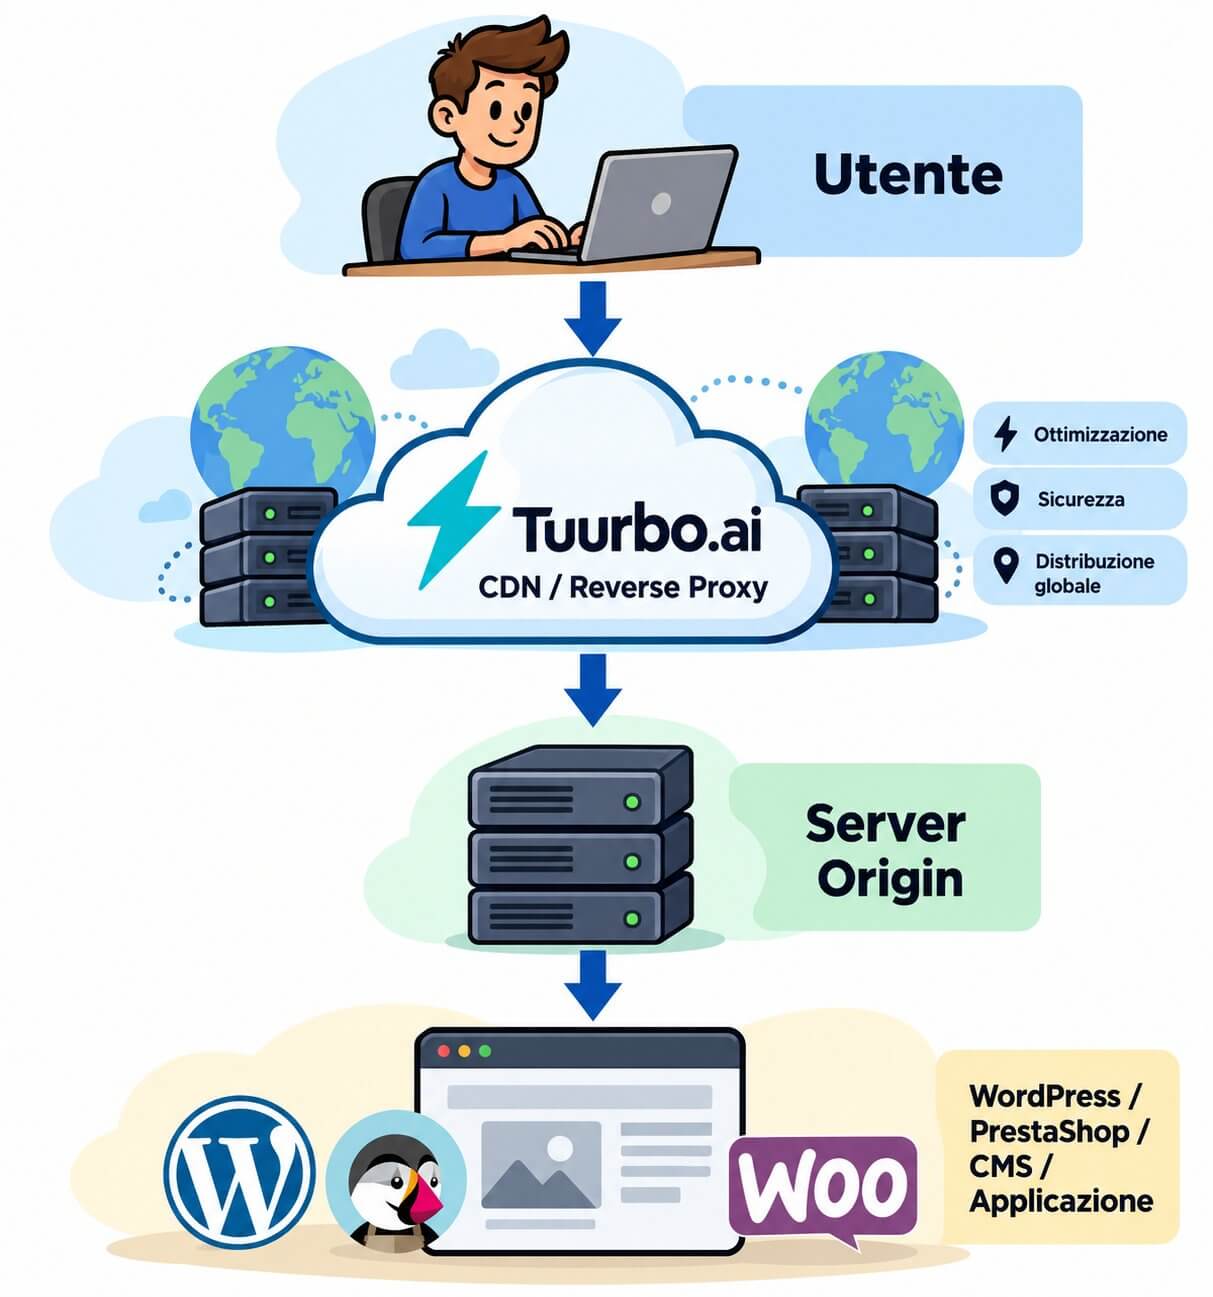
The architecture includes an intermediate layer that sits between the origin server and the visitor.
In infrastructure terms we can describe it as a CDN and reverse proxy based system.
When a user requests a page, the request may then pass through intermediate infrastructure before reaching the server actually hosting WordPress, PrestaShop, WooCommerce, or the client's application.
In a very simplified way:
The interesting point comes especially in the reverse path.
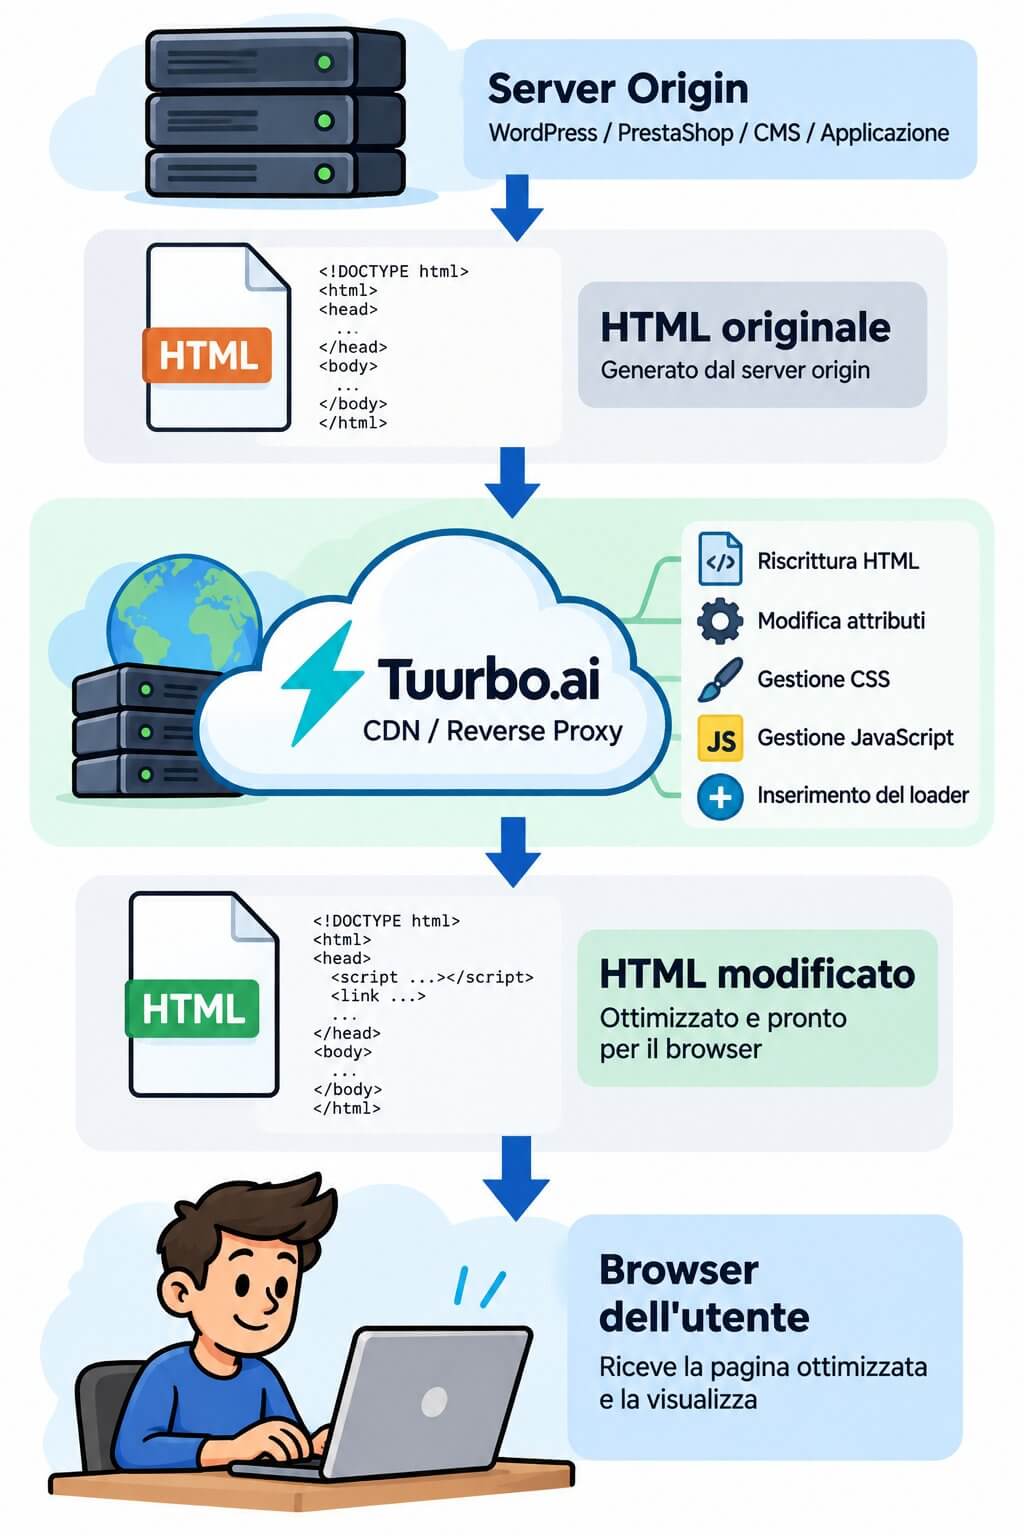
The origin server generates its own HTML, but that document can be intercepted and transformed before being delivered to the browser:
And this is where we need to distinguish this architecture from the simpler concept of a CDN.
A traditional CDN is typically associated with the geographic distribution of resources: images, CSS, JavaScript, fonts, and other files are stored in nodes geographically closest to the visitor, reducing latency and load on the origin.
But a reverse proxy can do much more.
It can directly modify the response produced by the server before delivering it to the client.
This means that the CMS can generate a certain HTML document and the user's browser can receive a different version of it.
For example, the server might produce:
<img src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" data-wp-preserve="%3Cscript%20src%3D%22%2Fjs%2Fapp.js%22%3E%3C%2Fscript%3E" data-mce-resize="false" data-mce-placeholder="1" class="mce-object mce-object-script" width="20" height="20" alt="&lt;script&gt;" />
As it passes through the optimization layer, this element can be conceptually transformed into something like this:
<img src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" data-wp-preserve="%3Cscript%20type%3D%22tuurbo%2Fjavascript%22%20data-tbdelay-src%3D%22%2Fjs%2Fapp.js%22%3E%3C%2Fscript%3E" data-mce-resize="false" data-mce-placeholder="1" class="mce-object mce-object-script" width="20" height="20" alt="&lt;script&gt;" />
The script still exists logically on the page, but for the browser it is no longer immediately executable JavaScript.
The original attribute is parked elsewhere and the loader will later decide when to restore and execute that resource.
The same principle can be used with CSS, images, iframes, and other elements.
HTML rewriting and DOM manipulation are two different phases
It is useful to make a technical distinction.
The first transformation occurs before the page reaches the browser.
At this stage, it would be inappropriate to actually talk about DOM manipulation, because the browser hasn't yet built a Document Object Model. There's an HTML response that the reverse proxy can parse and rewrite.
This is where attributes such as src, type e rel, inserted attributes data-*, modified resources and added the JavaScript required for the system to function.
Then the page arrives in Chrome, Firefox, Safari, or another browser.
The browser parses the HTML, builds the DOM, and then the second layer comes into play: the injected JavaScript can directly manipulate the document and the browser runtime.
It can create nodes, change attributes, replace elements, intercept calls, defer scripts, and artificially generate events.
We therefore have two distinct levels:
- HTML rewriting on the edge/reverse proxy side, before the document is delivered to the browser;
- Client-side manipulation of the DOM and JavaScript runtime, once the browser has started processing the page.
This distinction is important because it explains how optimizations can be applied without directly modifying the theme, plugin, or application source code.
The original site continues to generate one thing; the intermediate layer can deliver something else.
JavaScript injection allows you to orchestrate loading
The reverse proxy can temporarily disable some resources, but something is then needed to control their subsequent reactivation.
This is where the component that interests us most comes into play: the Tuurbo Loader.
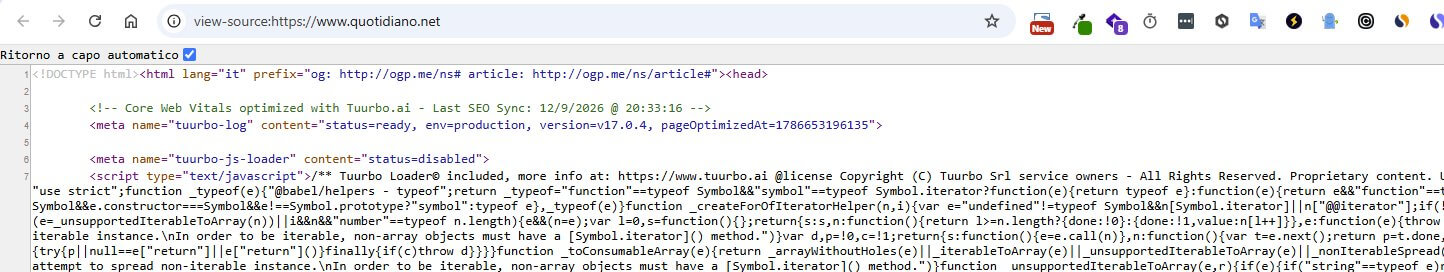
The loader can read the attributes introduced during the HTML transformation and decide when to unload, restore or execute the various components of the page.
From this point of view, we are not dealing with a simple analytics script tucked at the bottom of the document.
The loader becomes a real loading orchestrator.
It can decide when to run the originally present scripts, when to re-enable stylesheets, when to make certain images available, and when to simulate certain browser events.
And this is where the interesting part of our analysis begins.
The Loader: What It Really Does
The central component is called Tuurbo Loader and it is an inline script, minified and transpiled with Babel, injected into the affected pages.
The main mechanism is what is commonly called JavaScript delay.
The technique, taken by itself, is nothing strange.
It is also used by well-known tools such as WP Rocket, FlyingPress with the “Delay JavaScript execution” feature, Flying Scripts, and several other caching and performance plugins.
The principle is relatively simple.
Server side or edge, the normal tags <script> They are modified in such a way that the browser does not execute them immediately.
In the case analyzed, the attribute type becomes tuurbo/javascript, while the original attributes can be preserved within properties such as data-tbdelay-src e data-tbdelay-type.
For the browser, that is no longer a normal JavaScript script to execute during parsing.
This is where the loader comes into play.
Among the operations identified in the code are:
- Activation of LCP images marked with the class
tb-lazyload-lcp-image; - preloading blocking scripts through
<link rel="preload" as="script">; - sequential execution of render-blocking, async, and defer scripts;
- event generation synthetic including
DOMContentLoaded,readystatechangeeload; - the subsequent reactivation of previously neutralized stylesheets.
So far, technically, nothing particularly scandalous, but rather proof that the product complies with the best practices for PageSpeed optimization products and services.
It's an invasive approach, certainly complex and potentially fragile, but it can be used to achieve real benefits just as dozens of similar products and web developers have been doing for over a decade.
The problem is therefore not the JavaScript delay itself.
The really interesting point is to understand when the loader decides to start the scripts.
The three lines that change everything
In the loader we analyzed, a particularly significant constant appears:
DELAY_TIMING = {
DESKTOP: 1,
MOBILE: 1,
LIGHTHOUSE: 5e4
}
Values are expressed in milliseconds.
For a desktop visitor, JavaScript is reactivated with a delay of 1 millisecond.
For a mobile visitor the behavior is essentially the same.
For Lighthouse, however, the value is 5e4.
That is: 50.000 milliseconds.
Fifty seconds.
The point is not simply that Lighthouse gets a longer delay.
It's the order of magnitude that's interesting.
A fifty-second delay causes script execution to occur well beyond the normal window in which a Lighthouse audit completes its analysis of the page.
As a result, during much of the test, the site's original JavaScript is not executed.
And if the JavaScript isn't running, a huge amount of work disappears from the main thread during the audit.
No long tasks generated by those bundles.
No initialization of many widgets.
No carousel.
No popups.
No third-party code running within the normal measurement range.
The test therefore finds itself measuring a much lighter page than the one a real visitor uses in practice.
How Lighthouse is recognized
The loader contains a function called _isAgentLighthouse() which uses various signals to try to understand whether the browser loading the page is attributable to a Lighthouse environment or in any case automated.
Among the controls present in the analyzed code we identified elements such as:
/HeadlessChrome/.test(navigator.userAgent);navigator.webdriver;- controls based on
eval.toString(); - the presence of the string
headlessinsidenavigator.appVersion; - the search for references to
lighthouse,Chrome-Lighthouseemoto g powerin the user agent.
This last point is particularly interesting because the Moto G Power was used in mobile emulation environments related to the Lighthouse audits.
Taken alone, of course, detecting a headless browser proves nothing.
There are many legitimate reasons to want to distinguish an automated browser from a real visitor: anti-scraping, crawler management, abuse prevention, compatibility workarounds.
The situation changes when that detection is directly linked to a 50-second delay applied specifically to the branch identified as Lighthouse.
The detail that makes the behavior even more interesting
The analyzed code also features an explicit exclusion before some user agent checks:
if (
ua.indexOf("instagram") >= 0 ||
ua.indexOf("samsung") >= 0
) return false;
Basically, if the user agent contains references to Instagram or Samsung, that browser is not treated as Lighthouse through that detection branch.
One possible technical interpretation is that some false positives were handled.
Embedded browsers, Samsung Internet, and particular combinations of user agents may in fact share characteristics that risk interfering with overly aggressive fingerprinting systems.
And that's exactly what makes the behavior worthy of attention.
The detection appears to be sophisticated enough to attempt to distinguish a measurement environment from some browsers used by real people.
In the manager of DOMContentLoaded We also found that some operations, including those related to LCP image activation and preloading, are subject to a check of the type:
if (!this._isAgentLighthouse()) {
// attivazione e preload
}
During the audit, therefore, the behavior of the page may be significantly different from that reserved for the ordinary user.
Side effects on the DOM and JavaScript runtime
When you take control of a page's normal loading cycle, you inevitably have to rebuild some of the behaviors that the browser and libraries expect.
And this is where the loader becomes particularly invasive.
Among the changes observed in the code we find interventions on very deep components of the runtime.
document.readyState is redefined through Object.defineProperty.
This means that a library querying the document state may not necessarily receive the native value as it would have been produced by the normal browser lifecycle.
Wrappers or Proxies are also applied to DOM methods.
For example, Node.prototype.insertBefore It is intercepted in order to control the insertion of certain scripts.
In the analyzed code there is also a specific exception for an element identified as audiweb-action.
The Node.prototype.removeChild It is intercepted to handle the removal of some elements.
Other interventions concern:
- the rewriting of
document.writeedocument.writeln; - the use of
jQuery.holdReady(true)to temporarily suspend normal handlersready; - artificial event management
DOMContentLoadedeload; - the subsequent reactivation of scripts and stylesheets.
The reason is understandable.
If a WordPress plugin or PrestaShop script expects to run at DOMContentLoaded, but the loader intentionally prevented that script from starting at that time, you need to later artificially recreate the conditions that that software expected.
And this is where compatibility problems often begin.
Site-specific patches
Inside the loader we also found a number of specific fixes aimed at individual domains or certain applications.
The code contains workarounds related to, among other things:
- product carousel;
- duplicate cookie banners;
- authentication popup;
- Avada galleries;
- Slick slider;
- PrestaShop shopping carts;
- size and positioning of page elements.
In some cases, application events are manually triggered such as:
prestashop.emit("updateCart")
From a systems perspective, this is perfectly understandable.
When you fundamentally change the order in which JavaScript, CSS, and events are executed, some applications inevitably stop working as expected.
At that point, specific workarounds become necessary.
It's the classic cost of complexity.
The further you move away from the normal browser lifecycle, the more you have to manually compensate for the incompatibilities introduced.
Why PageSpeed Rises but CrUX Data May Remain Negative
We now come to the point that really matters to those who pay for an optimization service.
PageSpeed Insights puts two completely different families of data on the same screen.
On one hand we have the field data , coming from the Chrome User Experience Report, commonly referred to as CrUX.
This data is collected from the browsing experience of real Chrome users and aggregated over a period of time.
On the other hand, we have the laboratory test , produced through Lighthouse.
The famous score from 0 to 100 with the red, orange or green circle comes from laboratory testing.
And it is essential to understand that the two things are not equivalent.
Lighthouse runs a simulation.
CrUX observes what actually happens to visitors.
If the software recognizes Lighthouse and presents it with a different behavior, it is perfectly possible to simultaneously achieve:
98 or 100 in synthetic testing and Core Web Vitals not exceeded in real data.
There is no contradiction.
What Lighthouse Sees
If the application JavaScript is delayed by fifty seconds during the audit, Lighthouse can measure a page on which much of the work has not yet occurred.
Total Blocking Time can drop dramatically because many long tasks simply don't get executed.
The layout may be more stable because some widgets have not yet been initialized.
The main thread remains freer.
Popups, advertising, sliders, interactive components, and third-party scripts may not have really come into play yet.
The result is mathematically correct.
The problem is another:
that may not be the same experience served to the actual user.
What the user sees instead
For a normal browser, the delay identified in the code is one millisecond.
This means that JavaScript work is not deleted.
It is postponed.
And moving jobs doesn't necessarily mean reducing them.
In fact, in some cases artificially delaying numerous scripts can concentrate a large amount of work at a later stage of loading.
This can lead to problems with real-world metrics.
INP , Interaction to Next Paint, is particularly important because it measures the page's ability to respond to user interactions.
If the user clicks or taps something while the main thread is executing a large amount of deferred JavaScript, the delay becomes a real experience.
CLS can also be affected.
A delayed script can insert a banner, initialize a slider, change the height of a container, or dynamically add a widget after the page has already rendered.
The real browser records the movement.
A test that terminated before that script ran might not see it.
On the contrary, the LCP can really improve thanks to correct techniques such as prioritization and preloading of the main image.
And it's important to emphasize this: this doesn't mean that every optimization performed by the system is necessarily false or ineffective.
The problem arises when the configuration observed by the benchmark system differs significantly from that observed by real users.
PageSpeed score is not the site
This story once again highlights a misunderstanding that we continually encounter in performance projects.
PageSpeed Insights doesn’t measure “how fast a site is” with a single absolute number.
The Lighthouse score is a diagnostic index obtained through a specific testing methodology.
It's very useful.
We use it too.
But it needs to be interpreted.
A 100 achieved by making the page less representative of the real experience is worth much less than an 80 achieved by a page that actually does everything the user needs to use it.
It's like measuring a server's power consumption by temporarily disabling all heavy processes during the benchmark.
The number improves.
The real workload no.
This is not the first time we have observed this pattern.
We have already discussed conceptually similar behavior in our analysis of Kleecks, iSmartframe, and CDNs optimizing Core Web Vitals.
The general pattern is known:
- a layer is placed between the site and the visitor;
- that layer can modify the response;
- the system tries to identify the benchmark software;
- the benchmark may be given a behavior different from that of the real visitor;
- the customer then sees a vastly improved summary score.
From a commercial point of view, the advantage is clear: a score where everything is green sells much easier than a score of 70 orange.
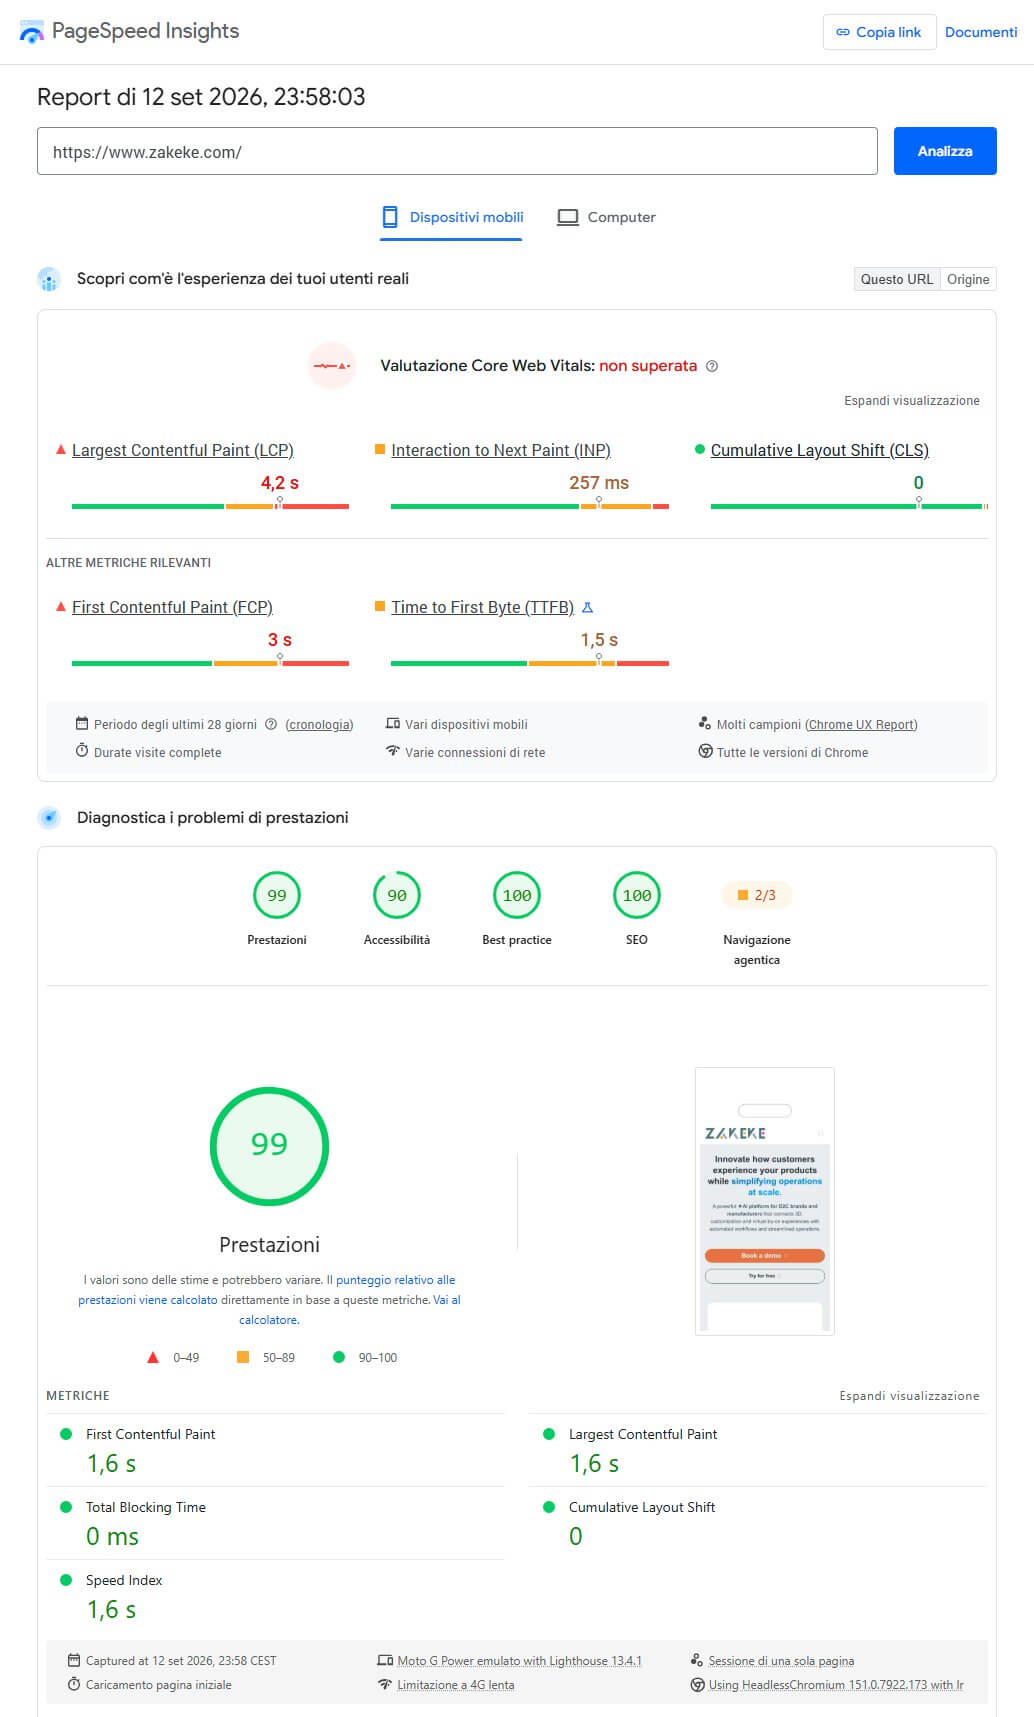
Truly optimizing a site often takes weeks of work.
You need to work on SQL queries, remove plugins, fix WordPress themes, reduce JavaScript, modify templates, analyze object and page caches, optimize images, fix external integrations, subset fonts, check slow APIs, and work on the database, and much, much, much more.
It is systemic and applicative work, artisanal and never automated.
It requires skills, access to code, and often collaboration with developers.
Increasing a synthetic score through an external layer is much easier to sell and much easier to show in a screenshot.
What do the AIs say about that Tuurbo Loader Javascript code?
We wanted to ask the main and most famous AI (Large Language Model) for their opinions on this loader, because we realize that some considerations that may emerge from our analysis above suggest at least questionable conduct regarding the transparency of the tests performed and therefore we felt it was right to ask for an impartial opinion, not necessarily a Tuurbo.ai review from the main LLMs based exclusively on the pasted loader code.
We involved the main 3 in order, with OpenAI's ChatGPT with the 5.6-Sol model, Gemini in the Pro version and finally Claude with Anthropic's Fable 5.1 model, the results were all quite clear, precise and consistent.
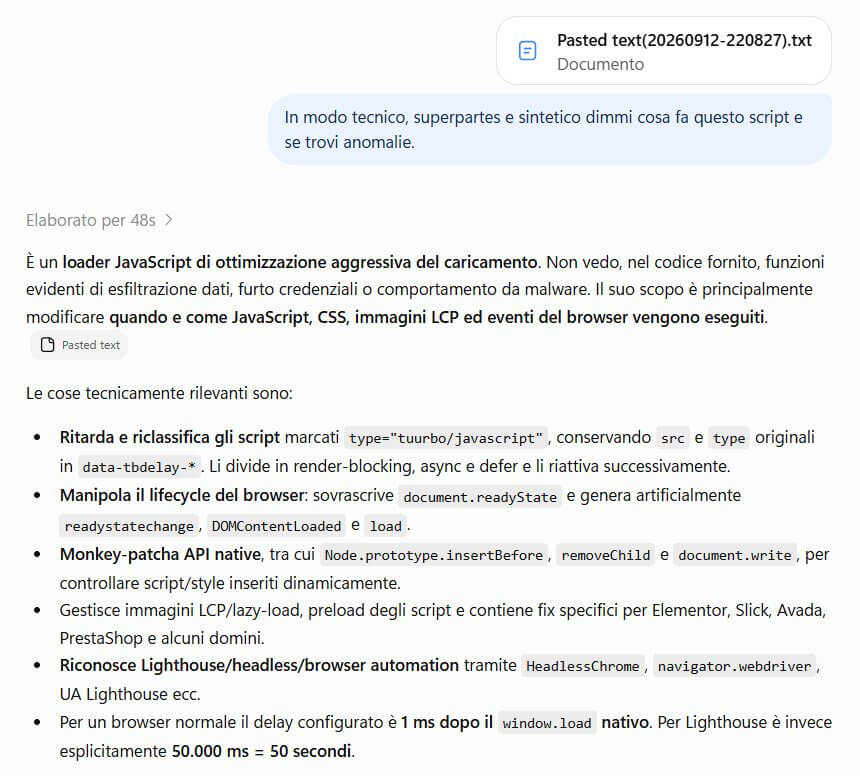
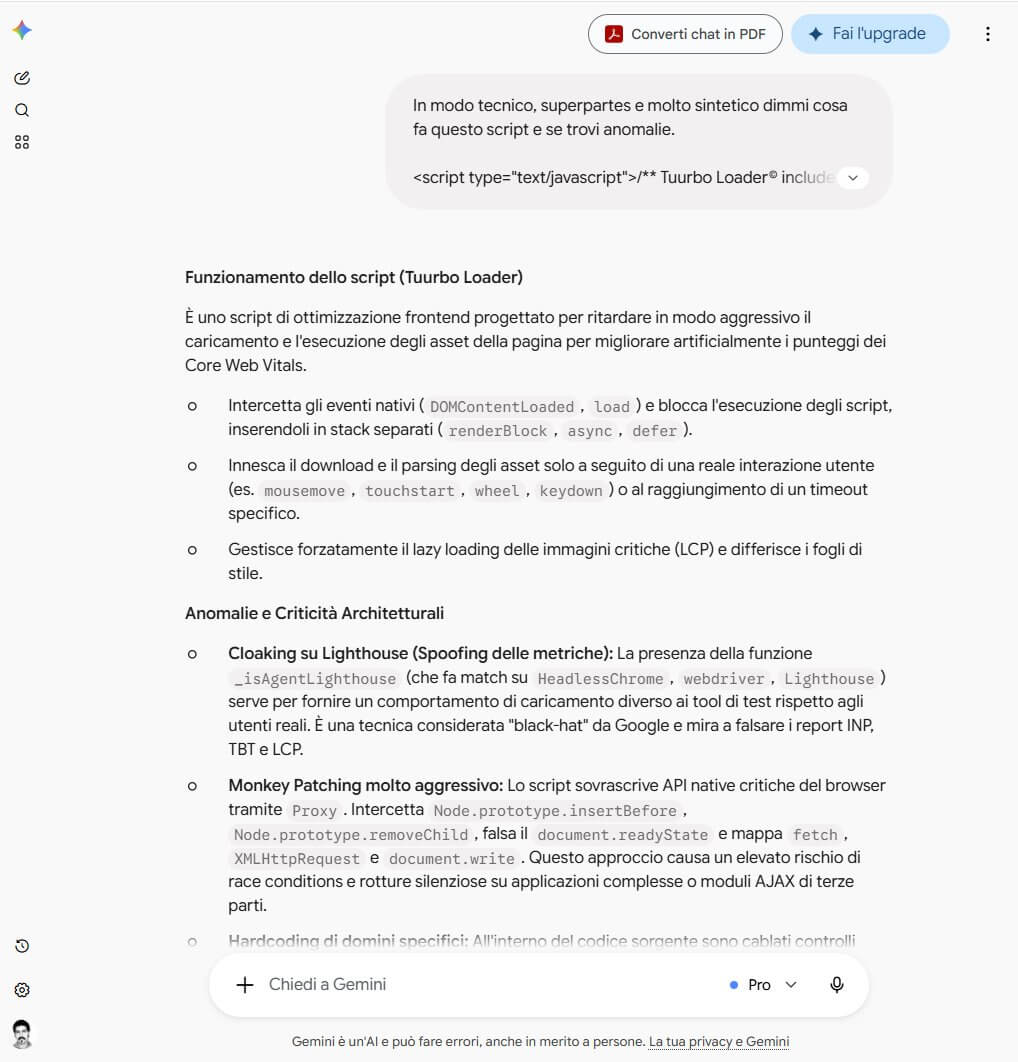
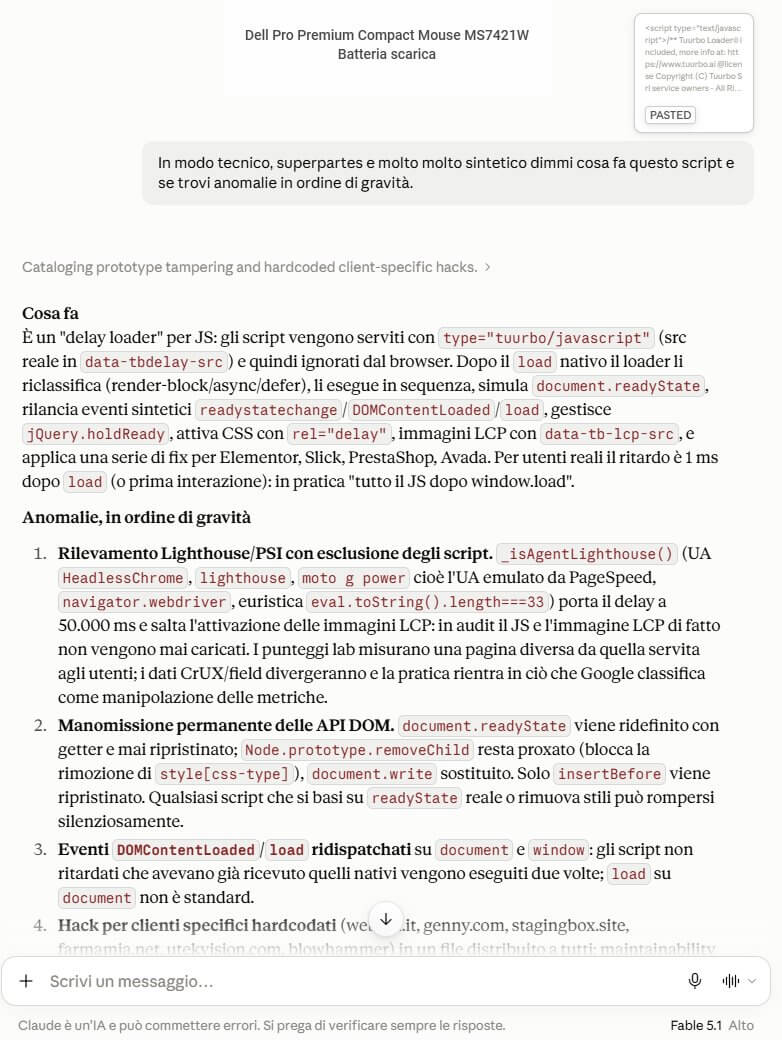
Despite the explicit request in the prompt to be impartial and very concise, Gemini gives a verdict as serious as it is merciless, going so far as to say bluntly:
It is a technique considered "black-hat" by Google and aims to distort INP, TBT and LCP reports.
However, what must be said in defense of Tuurbo.ai
It would be incorrect to turn this analysis into a “nothing works”.
That's not what we're advocating.
Several techniques used by the product are technically sound.
JavaScript delay is a real technique.
LCP image preloading is a real technique.
A CDN can produce real benefits.
Caching can produce real benefits.
Image transformation can produce real benefits.
Eliminating or deferring non-critical resources can actually make a page load faster.
A very heavy WordPress site could therefore actually perform better for a user after installing such a layer.
It is also true that headless browser detection has perfectly legitimate uses.
The point of our analysis is not to contest these techniques.
The key is the combination of Lighthouse environment-specific detection and a delay of 50.000 milliseconds.
LIGHTHOUSE: 5e4
It's hard to think of that value as a normal optimization applied uniformly to visitors.
The code we analyzed clearly distinguishes the behavior.
And this very distinction should give pause to those who use PageSpeed Insights as the main demonstration of the improvement achieved.
The comparison with a “defeat device”
The parallel that comes naturally is that with the so-called defeat devices that became famous with the Volkswagen case.
In 2015, it emerged that some vehicles were able to recognize certain conditions associated with homologation tests and modify their engine behavior accordingly.
The conceptual point was not just that there was a different modality.
It was that the measurement system observed a behavior that did not represent that normally present in real conditions of use.
Naturally, we are talking about completely different fields and the comparison should be understood exclusively on the level of logical mechanism.
In the case analyzed here we have a software that tries to recognize a benchmark environment and associates a different configuration to that branch:
DESKTOP: 1
MOBILE: 1
LIGHTHOUSE: 50000
Normal user: one millisecond.
Lighthouse: fifty seconds.
It is difficult to find a more concise representation of the problem.
The real test is real users
Ultimately, however, the problem solves itself by looking at the correct data.
If a page scores 100 in Lighthouse but still has insufficient LCP, CLS, or INP in the real data, the site has not addressed the Core Web Vitals issue.
It improved a benchmark.
And this is exactly why anyone who is serious about performance cannot stop at the PageSpeed screenshot.
You need to look at Search Console.
You have to look at CrUX.
You should use Real User Monitoring whenever possible.
You need to observe how your site behaves with authentic users, authentic devices, and authentic connections.
And, most importantly, you need to open Chrome DevTools and read the code.
Conclusions
Tuurbo.ai uses a technically interesting architecture.
A CDN and a reverse proxy allow you to intercept the origin response, rewrite the HTML, and inject a JavaScript loader.
The loader then takes control of an important part of the page lifecycle: it delays scripts, manages resources, manipulates the DOM, intercepts native methods, produces synthetic events, and applies specific workarounds.
Many of these techniques can be legitimately used to improve performance.
The point that we consider problematic is another.
In the loader we analyzed, there is a behavior specific to Lighthouse, with a delay of 50 seconds versus the one millisecond reserved for normal users.
This means that a synthetic audit may observe a page that is substantially different than the one a person actually uses.
And it's a very plausible explanation for the phenomenon we started from:
PageSpeed Insights almost perfect and real Core Web Vitals still insufficient.
For anyone running a website, the most important lesson isn't even about Tuurbo.
It's about how you evaluate performance.
A green circle with 100 written on it is not a certification.
It is not an isolated ranking factor.
It doesn't demonstrate that users are getting a good experience.
It is a synthetic test, performed under precise conditions.
If you really want to know how fast a site is, look at what happens outside the lab.
Look at a real user's browser.
Look at the main thread.
Look at the INP.
Look at the CLS.
Check out the CrUX.
And when the numbers seem too good to be compatible with what you're observing in the field, do the simplest thing of all:
open the source and read the code.
This analysis is based on reading JavaScript loader version 19.0.1 detected in production on third-party sites in 2026. The technical descriptions refer to the behavior observed in the code also analyzed by AI (Claude and ChatGPT). The assessments of the purpose and consequences of this behavior represent our personal technical interpretation. The software is subject to evolution, and subsequent versions may feature different implementations.

